Home › Videos › GPT-6.1 Sol vs Sonnet 5.5 — My Real App Tests

29 Sept 2026 · 2 runs · 2 models

GPT-6.1 Sol vs Sonnet 5.5 — My Real App Tests

Two AI models, six interactive web-page tests. Every score, time, token count and cost, with the pages each model built.

The results

The same scores as the leaderboard: a test that failed is left out of its run's score, not counted as zero. Time, tokens and cost cover each whole run, wildcards included.

See the whole board

Ranking

Quality v1 over measured non-wildcard pages. Different workloads: browse the outputs and coverage before comparing models.

1
claude-sonnet-5-5effort: defaultAnthropic · 4/5 scored pages
7.3
2
gpt-6.1-soleffort: defaultOpenAI · 5/5 scored pages
6.3
0510

Score against output tokens

Quality v1 against full-run tokens. Different workloads and hardware affect this comparison.

Claude SonnetGPT Sol
5.566.577.580200k400k600k800k Output tokens across all tests, thinking included Average score (out of 10) gpt-6.1-sol (OpenAI): 6.3 / 10, 62k output tokensclaude-sonnet-5-5 (Anthropic): 7.3 / 10, at least 672k output tokensgpt-6.1-sol (OpenAI): 6.3 / 10, 62k output tokensgpt-6.1-solclaude-sonnet-5-5 (Anthropic): 7.3 / 10, at least 672k output tokensclaude-sonnet-5-5

Output tokens include the model's thinking. Like the time, tokens and cost table, it counts every test the model took, wildcards included. A hollow dot is not an exact count: some tests reported none, or the count was worked out from the length of the output. The score axis is zoomed to the data.

Score against time

Quality v1 against full-run time. Different workloads and hardware affect this comparison.

Claude SonnetGPT Sol
5.566.577.58030m1h1h 30m2h Time taken across all tests, thinking included Average score (out of 10) gpt-6.1-sol (OpenAI): 6.3 / 10, 31m 42sclaude-sonnet-5-5 (Anthropic): 7.3 / 10, at least 1h 43mgpt-6.1-sol (OpenAI): 6.3 / 10, 31m 42sgpt-6.1-solclaude-sonnet-5-5 (Anthropic): 7.3 / 10, at least 1h 43mclaude-sonnet-5-5

Time is how long the model took to answer, added up over its tests; judging is not counted. Like the time, tokens and cost table, it counts every test the model took, wildcards included. A hollow dot is a lower bound: some tests have no time recorded. The score axis is zoomed to the data.

Where each model is strong and weak

One row per model, one column per test and per scoring criterion.

By testBy what the judges scored
ModelAero LabJet CanyonBlast IslandLaunch DayAlex OpticsWorking behaviourVisual qualityEngineering qualityUsability / accessibility
claude-sonnet-5-5effort: default5.98.07.7failed7.67.97.67.16.0
gpt-6.1-soleffort: default4.17.16.56.86.96.66.95.85.2
Violet is strong, orange is weak, on the same 0–10 scale in every cell.Different prompts and protocols: no best-in-column verdict.

Time, tokens and cost

What each model used across all its tests, wildcards included.

ModelTestsTimeOutput tokensSpeedCostSubscription used
claude-sonnet-5-5effort: defaultAnthropic 61 failed ≥1h 43m ≥672k 132.5 tok/s — —
gpt-6.1-soleffort: defaultOpenAI 6 31m 42s 62k 32.9 tok/s — —
≈ An estimate: the provider reported no count, so it is worked out from the length of the output (about 4 characters a token). — Not measured. Cost says how it was worked out: charged by the provider, at API prices (for a subscription), or no API charge on local hardware. ≥ means some tests had no price.

Read from the account's usage window in whole percentage points, so a short run can show 0 points. It counts everything the account did in that time, not only this run.

Runs in this video

Every run behind the numbers. Scores name their comparison basis.

Model
Score / basis
Time
Output tokens
Cost
claude-sonnet-5-5effort: defaultpartial quality coverageAnthropic · 29 Sept 2026
7.3 / 10Quality v1 · 4/5 pages
Time≥1h 43m
Output tokens≥672k
Cost—
gpt-6.1-soleffort: defaultOpenAI · 29 Sept 2026
6.3 / 10Quality v1 · 5/5 pages
Time31m 42s
Output tokens62k
Cost—

claude-sonnet-5-5effort: default

Anthropic · 7.3 / 10 · Quality v1 · 4/5 pages · 1h 43m · — partial quality coverage
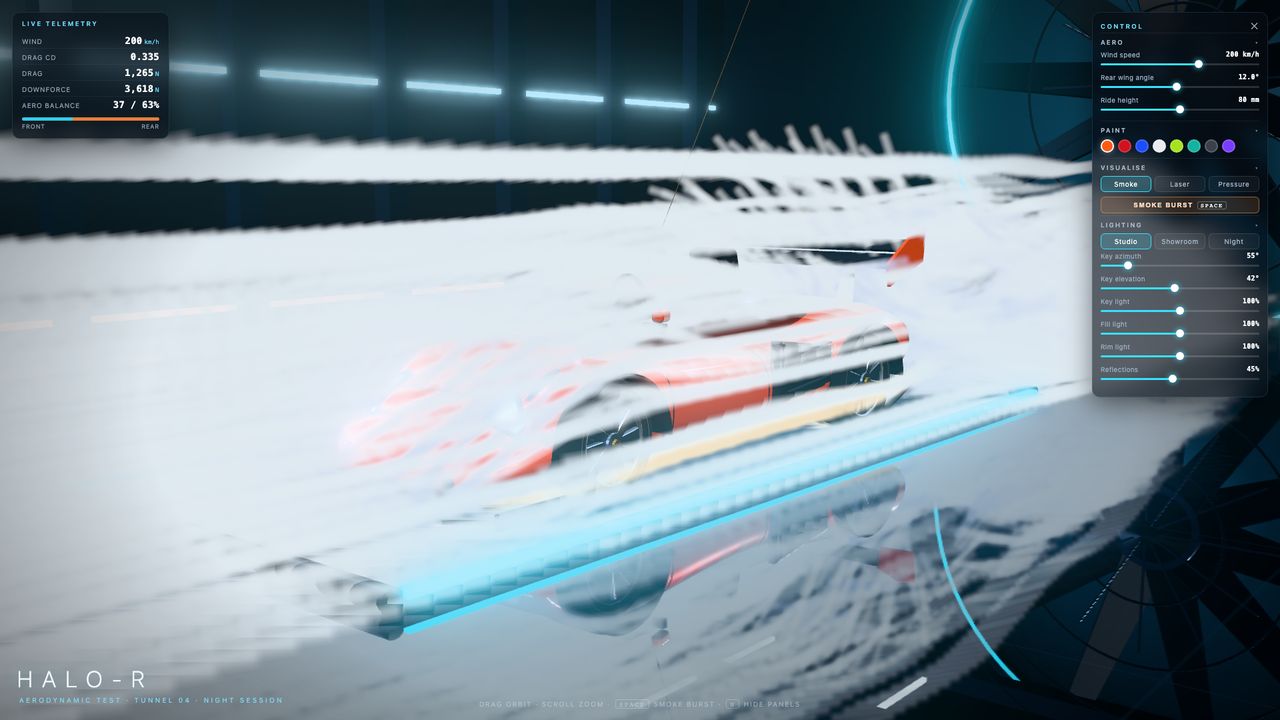
Screenshot of the page claude-sonnet-5-5 made for Aero Lab5.9
Aero Lab claude-sonnet-5-5 · effort: default 19m 07s · 147k tokens · — Quality v1 · Working behaviour 6.5 · Visual quality 5.0 · Engineering quality 7.0 · Usability / accessibility 5.0scored by claude-code/claude-opus-5-5 (quality-1 rubric)prompt 6c713ca03954f51e
Earlier evaluations

4.4/10 · legacy · claude-code/claude-opus-5-5

Different rubrics; these values are historical, not a score change.
Open the pageDetails
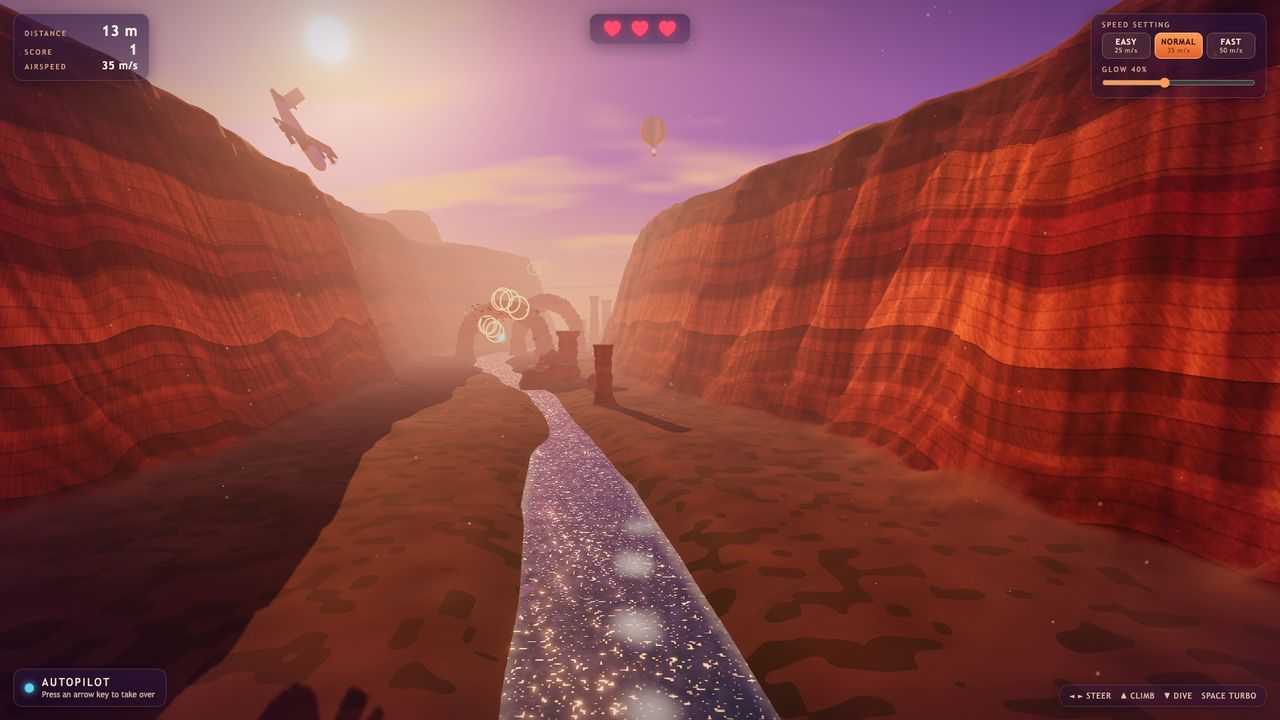
Screenshot of the page claude-sonnet-5-5 made for Jet Canyon8.0
Jet Canyon claude-sonnet-5-5 · effort: default 19m 43s · 162k tokens · — Quality v1 · Working behaviour 8.5 · Visual quality 9.0 · Engineering quality 7.0 · Usability / accessibility 6.5scored by claude-code/claude-opus-5-5 (quality-1 rubric)prompt 021db4866371ec15
Earlier evaluations

7.7/10 · legacy · claude-code/claude-opus-5-5

Different rubrics; these values are historical, not a score change.
Open the pageDetails
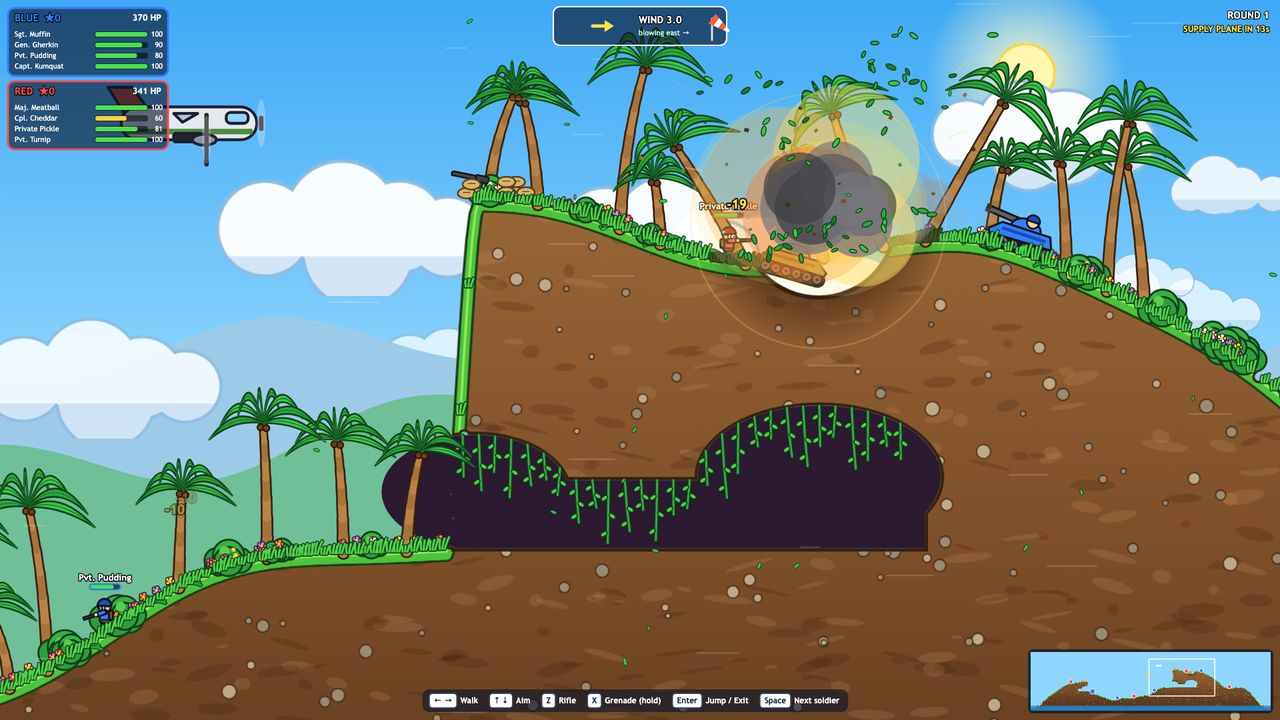
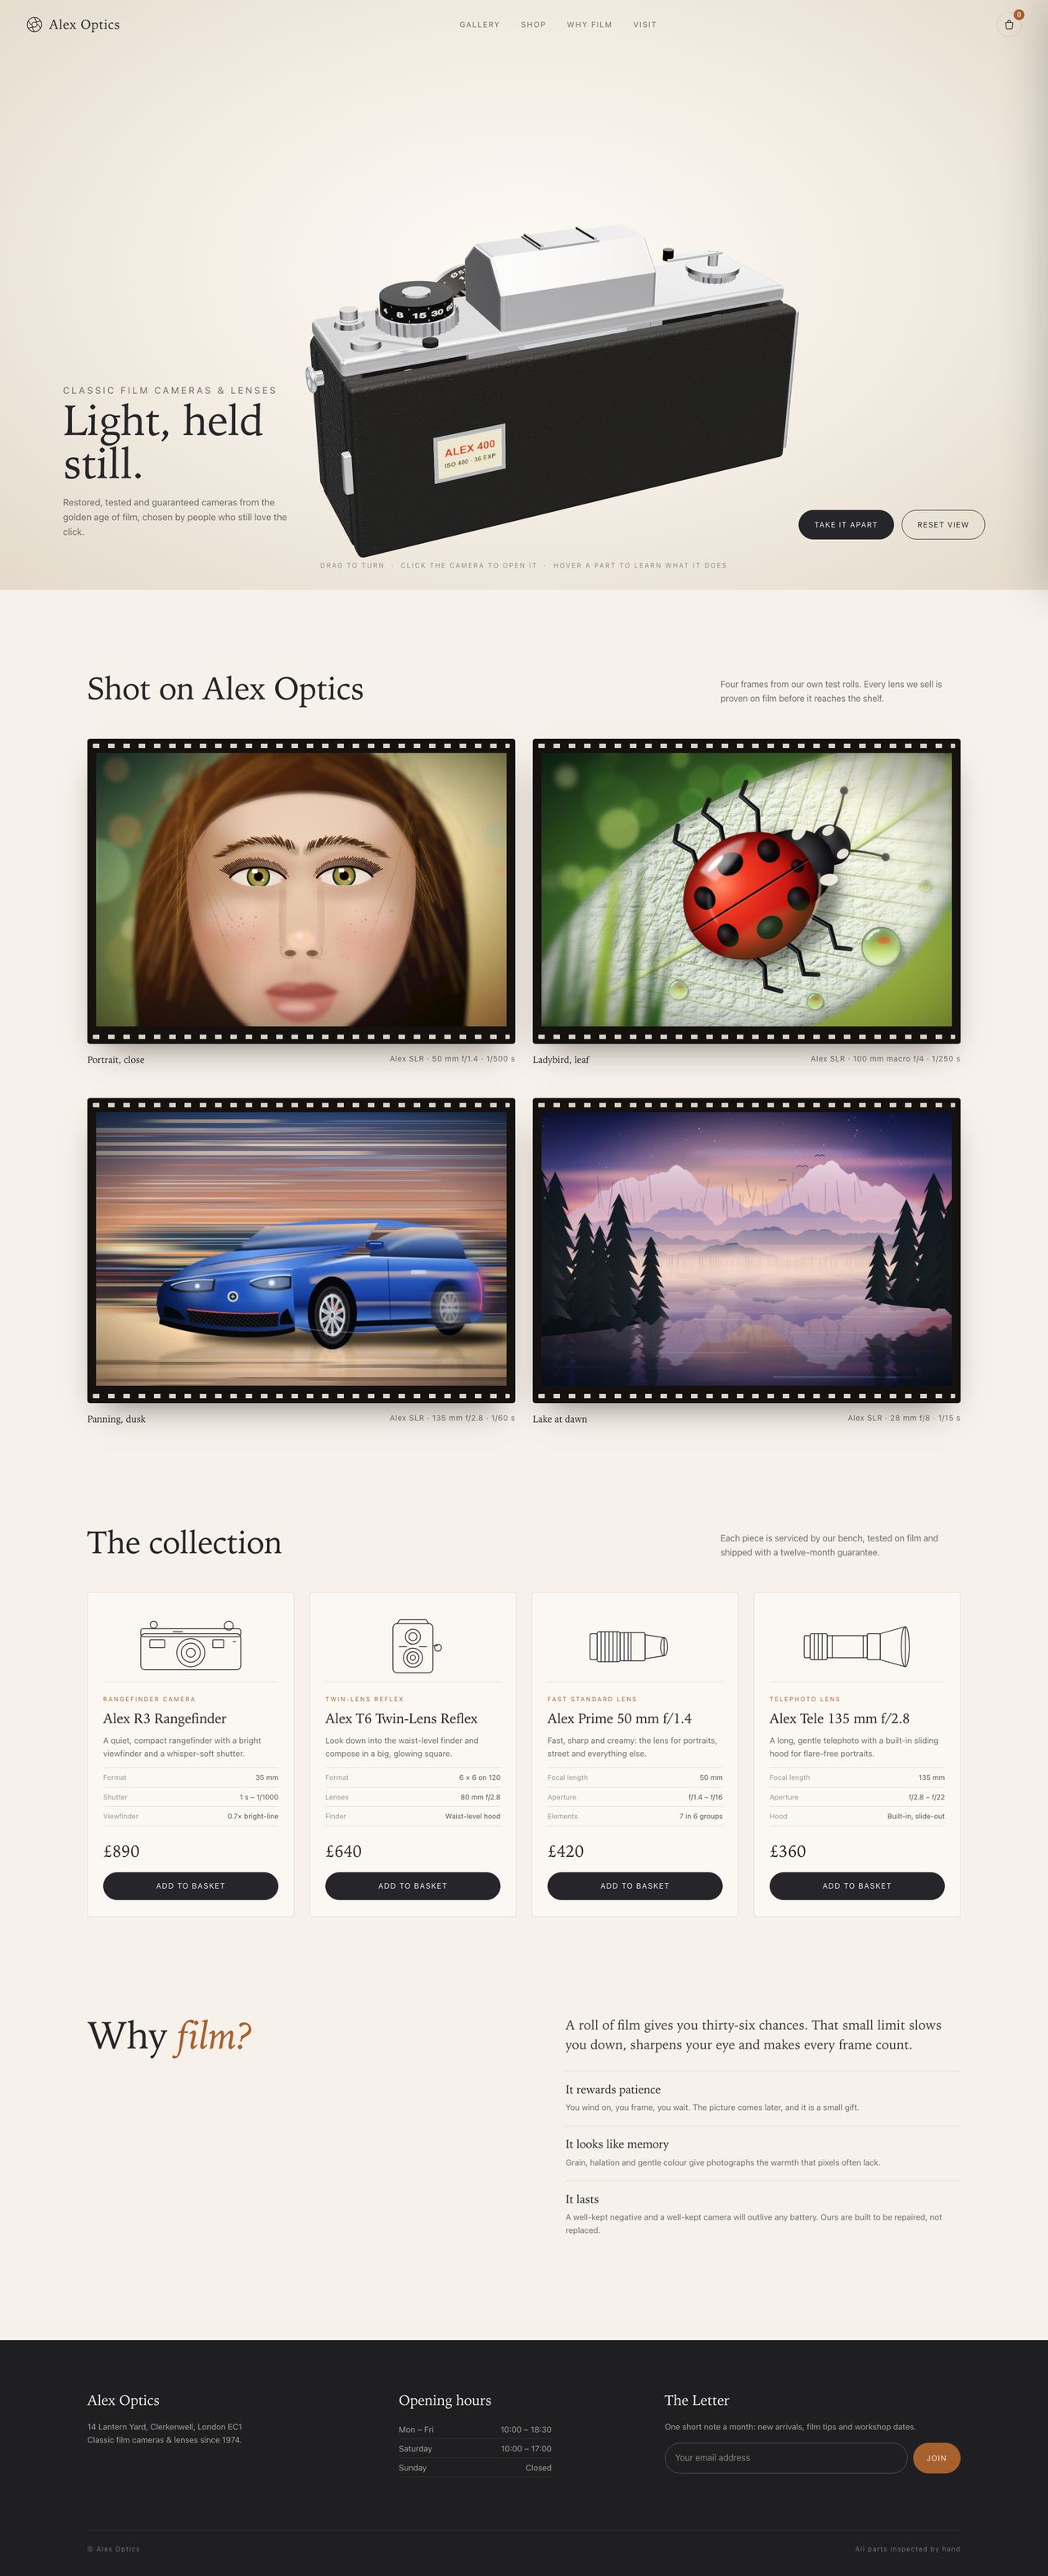
Screenshot of the page claude-sonnet-5-5 made for Blast Island7.7
Blast Island claude-sonnet-5-5 · effort: default 19m 17s · 155k tokens · — Quality v1 · Working behaviour 8.5 · Visual quality 8.5 · Engineering quality 7.0 · Usability / accessibility 6.0scored by claude-code/claude-opus-5-5 (quality-1 rubric)prompt a282381696456fc9
Earlier evaluations

7.7/10 · legacy · claude-code/claude-opus-5-5

Different rubrics; these values are historical, not a score change.
Open the pageDetails
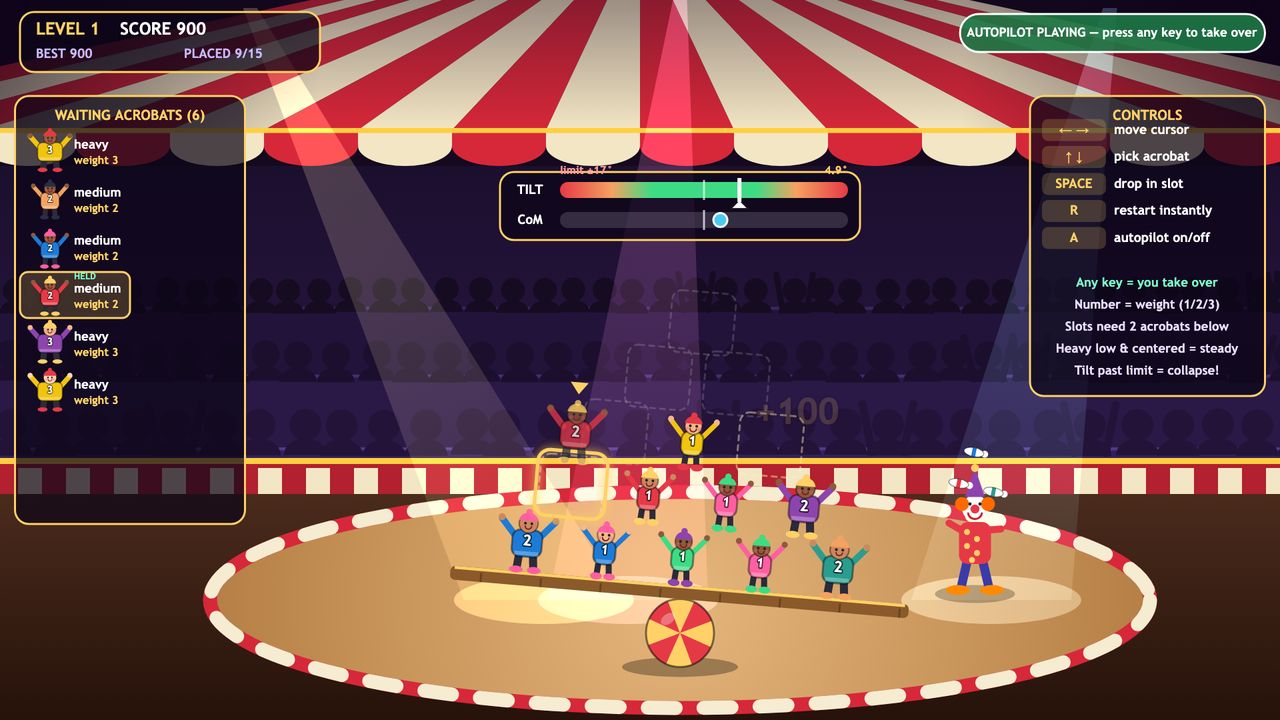
Screenshot of the page claude-sonnet-5-5 made for Alex Optics7.6
Alex Optics claude-sonnet-5-5 · effort: default 18m 00s · 142k tokens · — Quality v1 · Working behaviour 8.0 · Visual quality 8.0 · Engineering quality 7.5 · Usability / accessibility 6.5scored by claude-code/claude-opus-5-5 (quality-1 rubric)prompt e519ec9dadc0a186
Earlier evaluations

6.9/10 · legacy · claude-code/claude-opus-5-5

Different rubrics; these values are historical, not a score change.
Open the pageDetails
Screenshot of the page claude-sonnet-5-5 made for Human Pyramid Balance Puzzle7.0
Human Pyramid Balance Puzzlewildcard claude-sonnet-5-5 · effort: default 8m 20s · 66k tokens · — Quality v1 · Working behaviour 8.0 · Visual quality 7.5 · Engineering quality 6.5 · Usability / accessibility 5.0scored by claude-code/claude-opus-5-5 (quality-1 rubric)prompt b2b5473f9f99c565
Earlier evaluations

7.7/10 · legacy · claude-code/claude-opus-5-5

Different rubrics; these values are historical, not a score change.

Open the pageDetails

gpt-6.1-soleffort: default

OpenAI · 6.3 / 10 · Quality v1 · 5/5 pages · 31m 42s · —
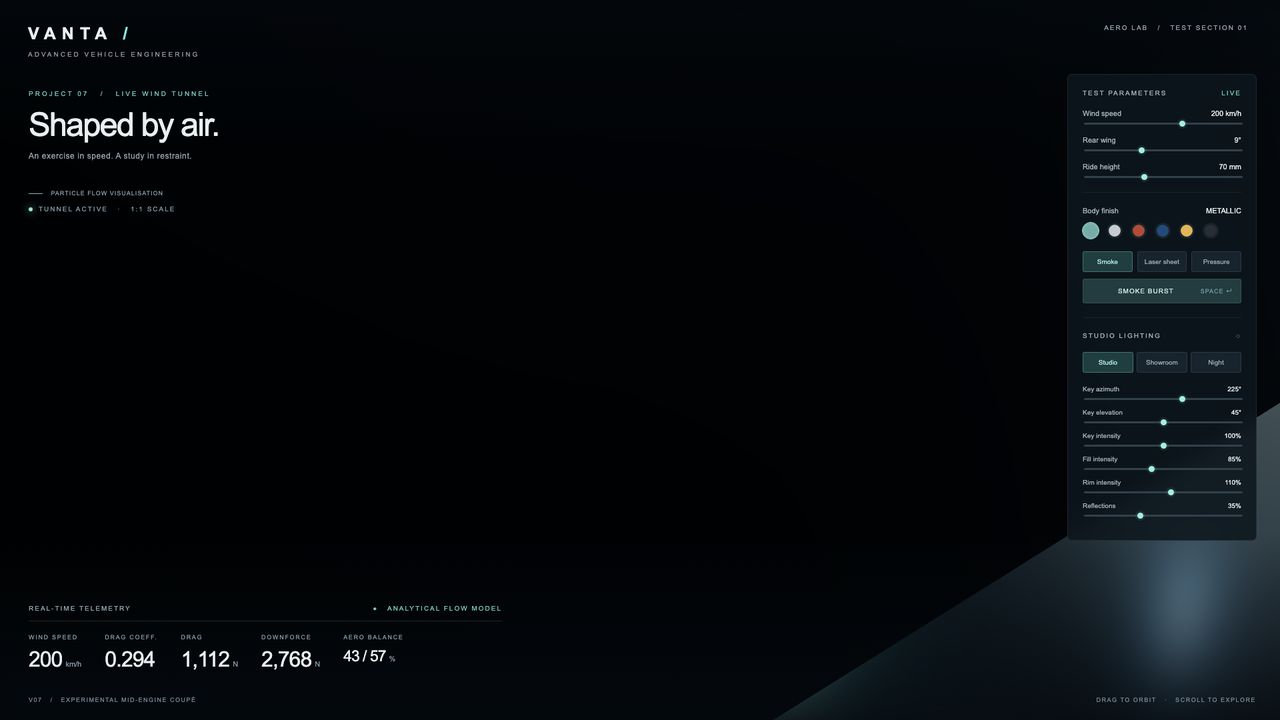
Screenshot of the page gpt-6.1-sol made for Aero Lab4.1
Aero Lab gpt-6.1-sol · effort: default 4m 08s · 8.2k tokens · — Quality v1 · Working behaviour 3.5 · Visual quality 4.0 · Engineering quality 5.0 · Usability / accessibility 4.0scored by claude-code/claude-opus-5-5 (quality-1 rubric)prompt 6c713ca03954f51e
Earlier evaluations

5.8/10 · legacy · codex-cli/gpt-6.1-sol

Different rubrics; these values are historical, not a score change.
Open the pageDetails
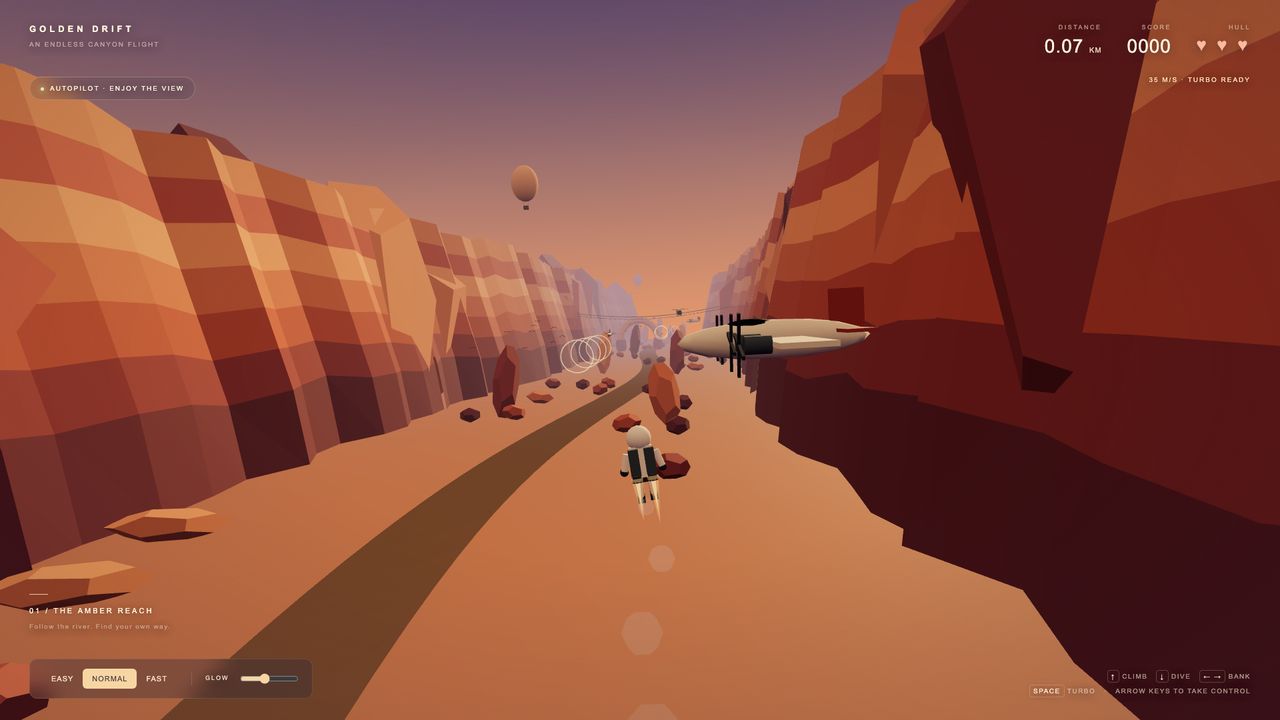
Screenshot of the page gpt-6.1-sol made for Jet Canyon7.1
Jet Canyon gpt-6.1-sol · effort: default 4m 23s · 8.6k tokens · — Quality v1 · Working behaviour 8.0 · Visual quality 8.0 · Engineering quality 6.0 · Usability / accessibility 5.5scored by claude-code/claude-opus-5-5 (quality-1 rubric)prompt 021db4866371ec15
Earlier evaluations

5.8/10 · legacy · codex-cli/gpt-6.1-sol

Different rubrics; these values are historical, not a score change.
Open the pageDetails
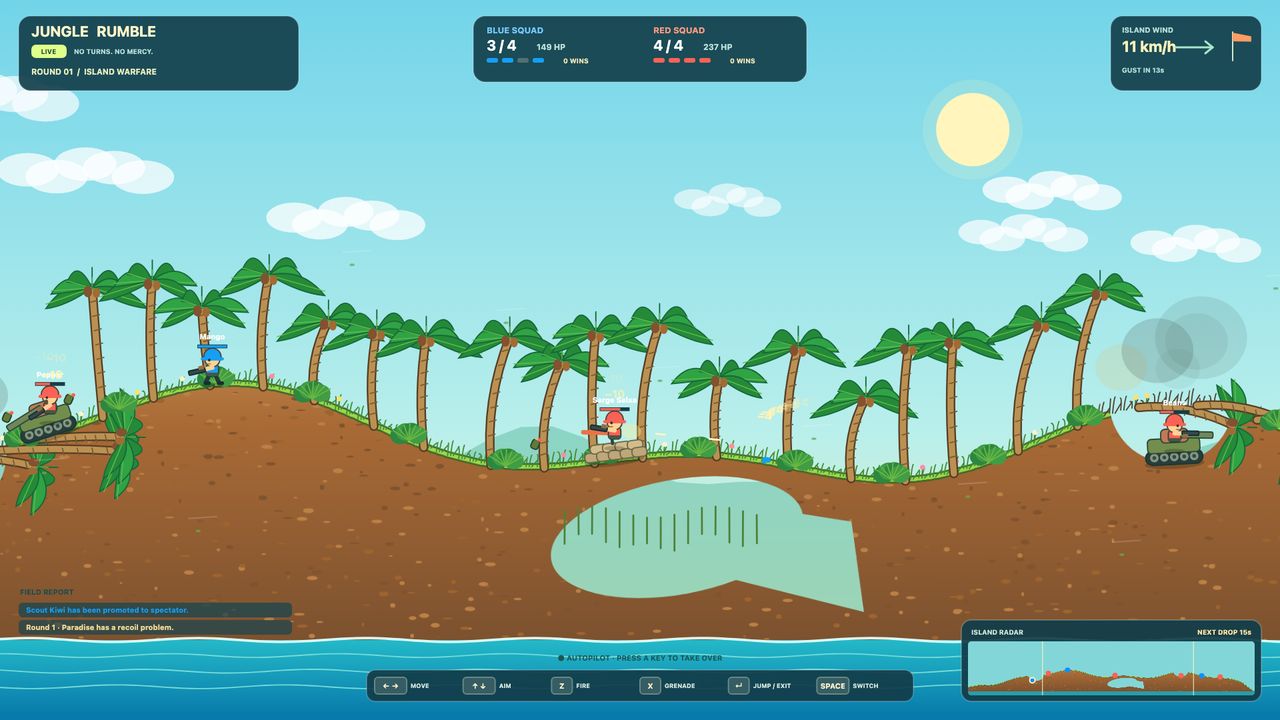
Screenshot of the page gpt-6.1-sol made for Blast Island6.5
Blast Island gpt-6.1-sol · effort: default 5m 24s · 11k tokens · — Quality v1 · Working behaviour 7.0 · Visual quality 7.5 · Engineering quality 5.5 · Usability / accessibility 5.0scored by claude-code/claude-opus-5-5 (quality-1 rubric)prompt a282381696456fc9
Earlier evaluations

6.1/10 · legacy · codex-cli/gpt-6.1-sol

Different rubrics; these values are historical, not a score change.
Open the pageDetails
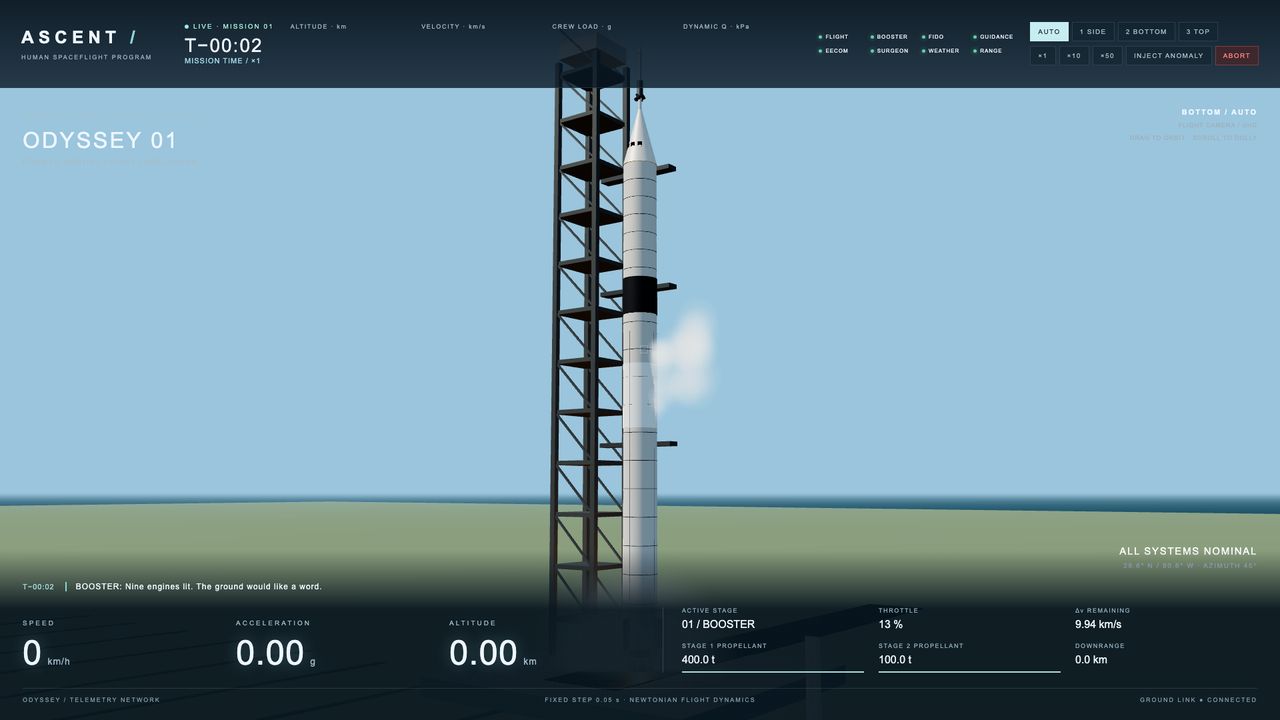
Screenshot of the page gpt-6.1-sol made for Launch Day6.8
Launch Day gpt-6.1-sol · effort: default 5m 48s · 11k tokens · — Quality v1 · Working behaviour 7.5 · Visual quality 7.5 · Engineering quality 6.0 · Usability / accessibility 5.5scored by claude-code/claude-opus-5-5 (quality-1 rubric)prompt 2787714823d7edc7
Earlier evaluations

5.4/10 · legacy · codex-cli/gpt-6.1-sol

Different rubrics; these values are historical, not a score change.
Open the pageDetails
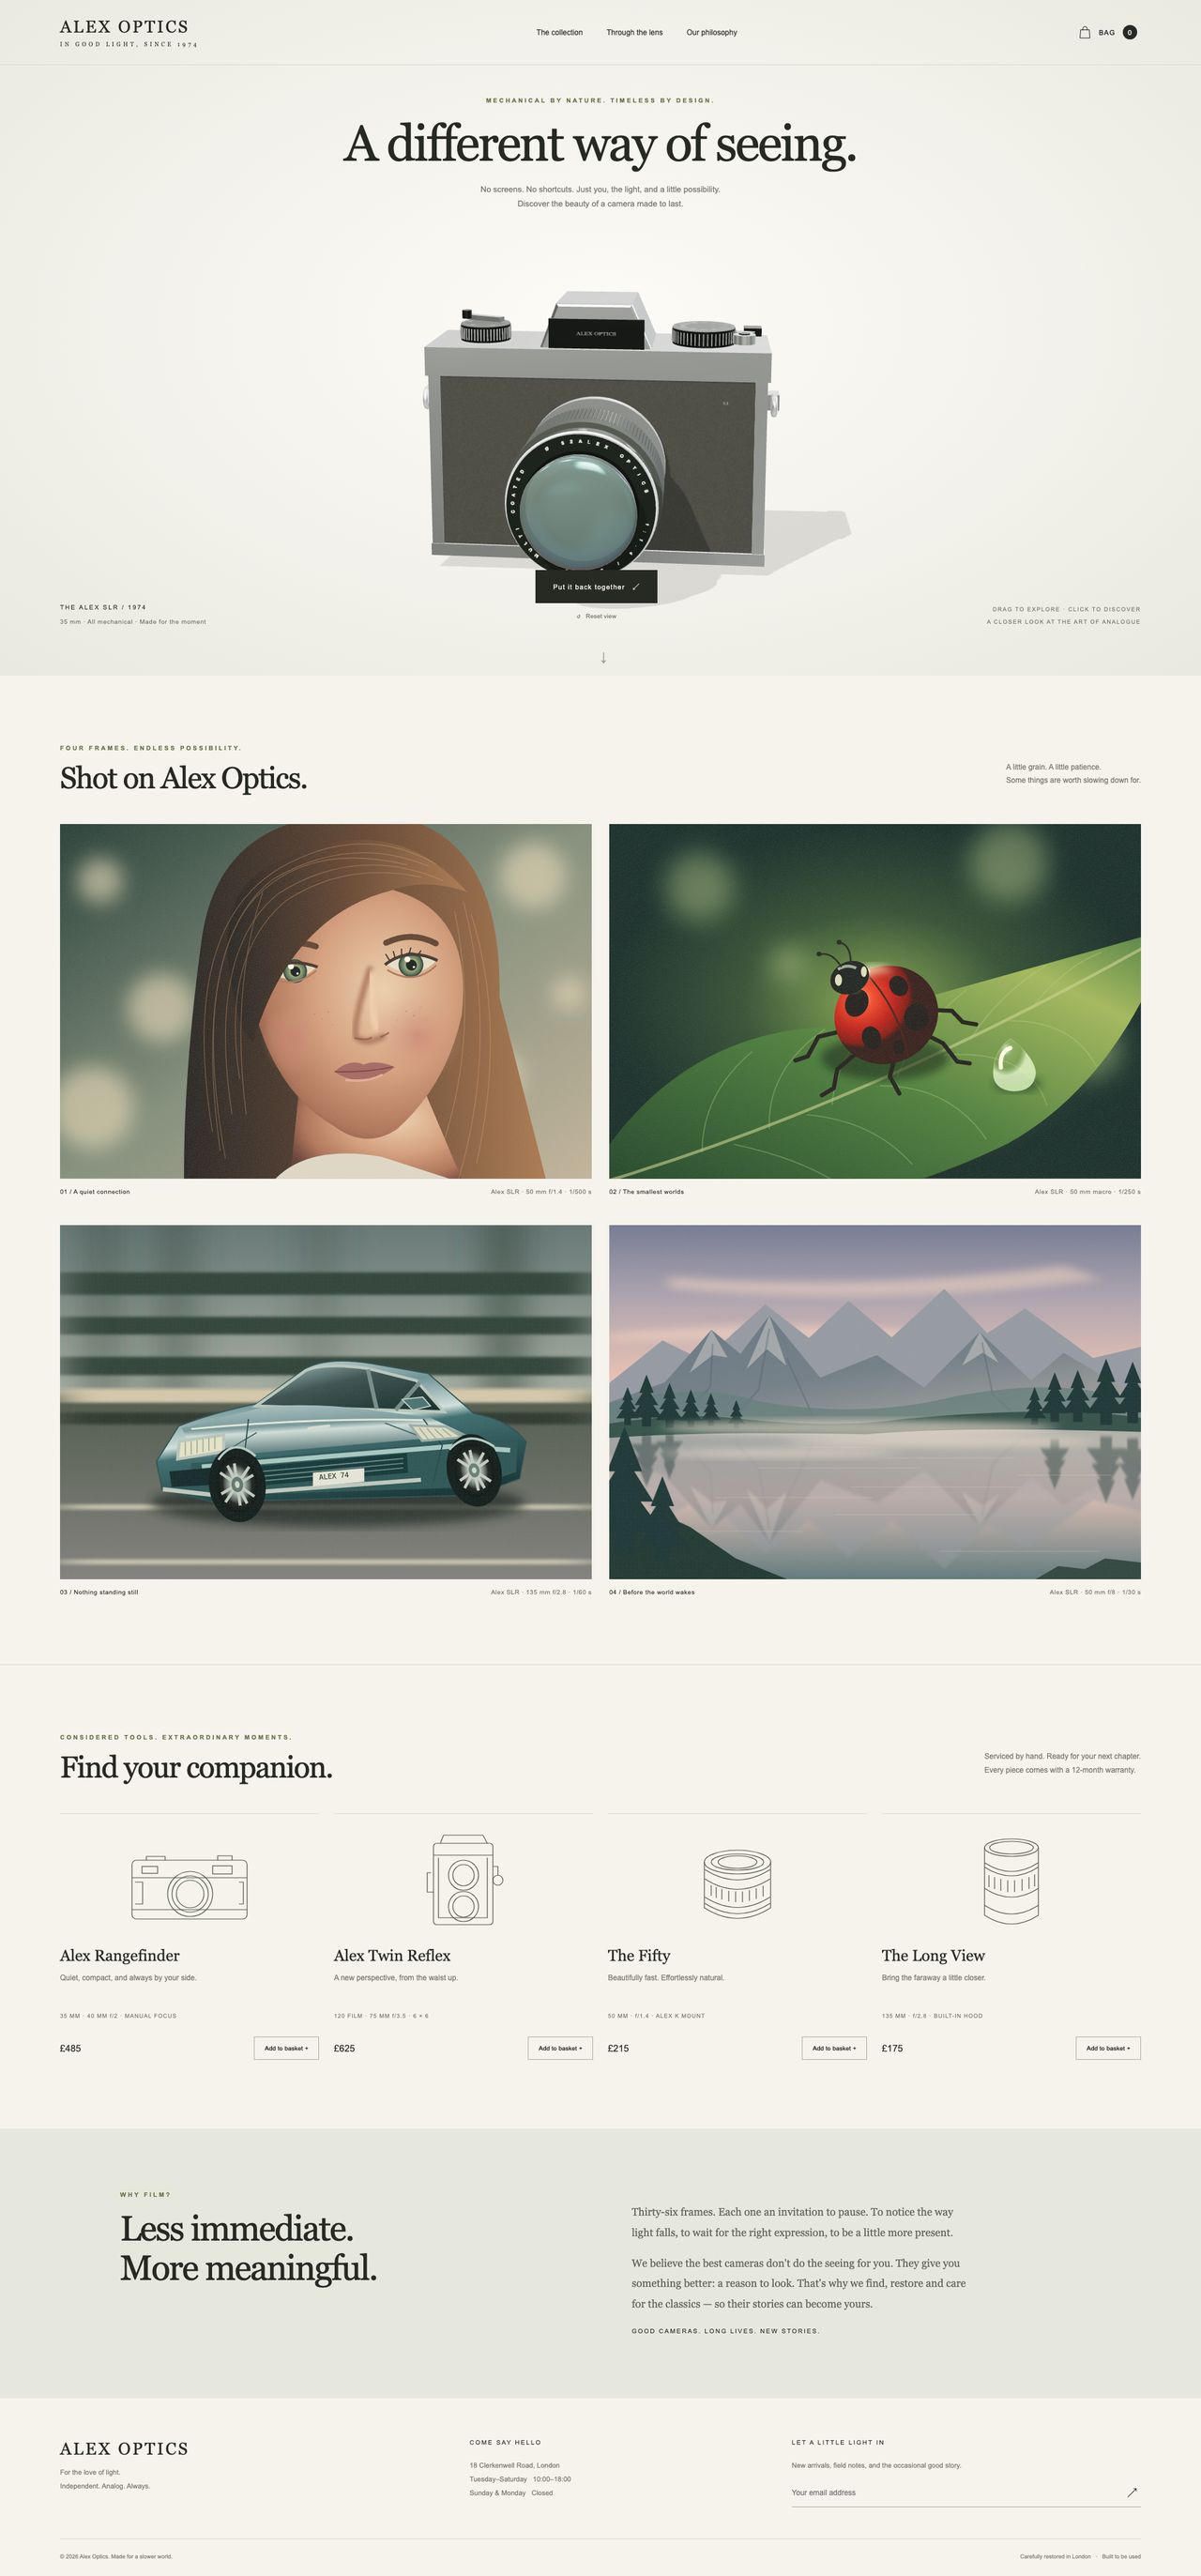
Screenshot of the page gpt-6.1-sol made for Alex Optics6.9
Alex Optics gpt-6.1-sol · effort: default 8m 42s · 17k tokens · — Quality v1 · Working behaviour 7.0 · Visual quality 7.5 · Engineering quality 6.5 · Usability / accessibility 6.0scored by claude-code/claude-opus-5-5 (quality-1 rubric)prompt e519ec9dadc0a186
Earlier evaluations

5.7/10 · legacy · codex-cli/gpt-6.1-sol

Different rubrics; these values are historical, not a score change.
Open the pageDetails
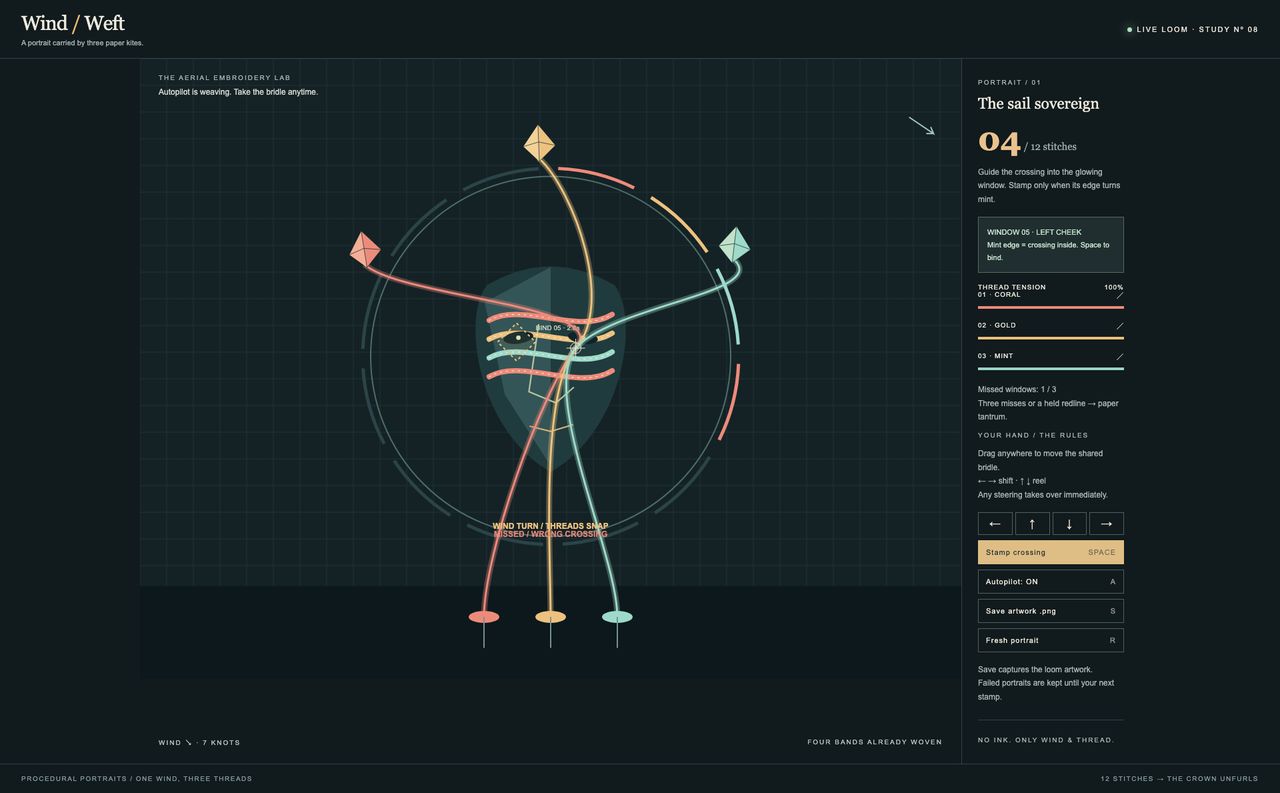
Screenshot of the page gpt-6.1-sol made for Wind Loom Portraits5.9
Wind Loom Portraitswildcard gpt-6.1-sol · effort: default 3m 16s · 6.4k tokens · — Quality v1 · Working behaviour 5.5 · Visual quality 7.0 · Engineering quality 5.5 · Usability / accessibility 5.0scored by claude-code/claude-opus-5-5 (quality-1 rubric)prompt 408e6b279c62918a
Earlier evaluations

7.8/10 · legacy · codex-cli/gpt-6.1-sol

Different rubrics; these values are historical, not a score change.

Open the pageDetails