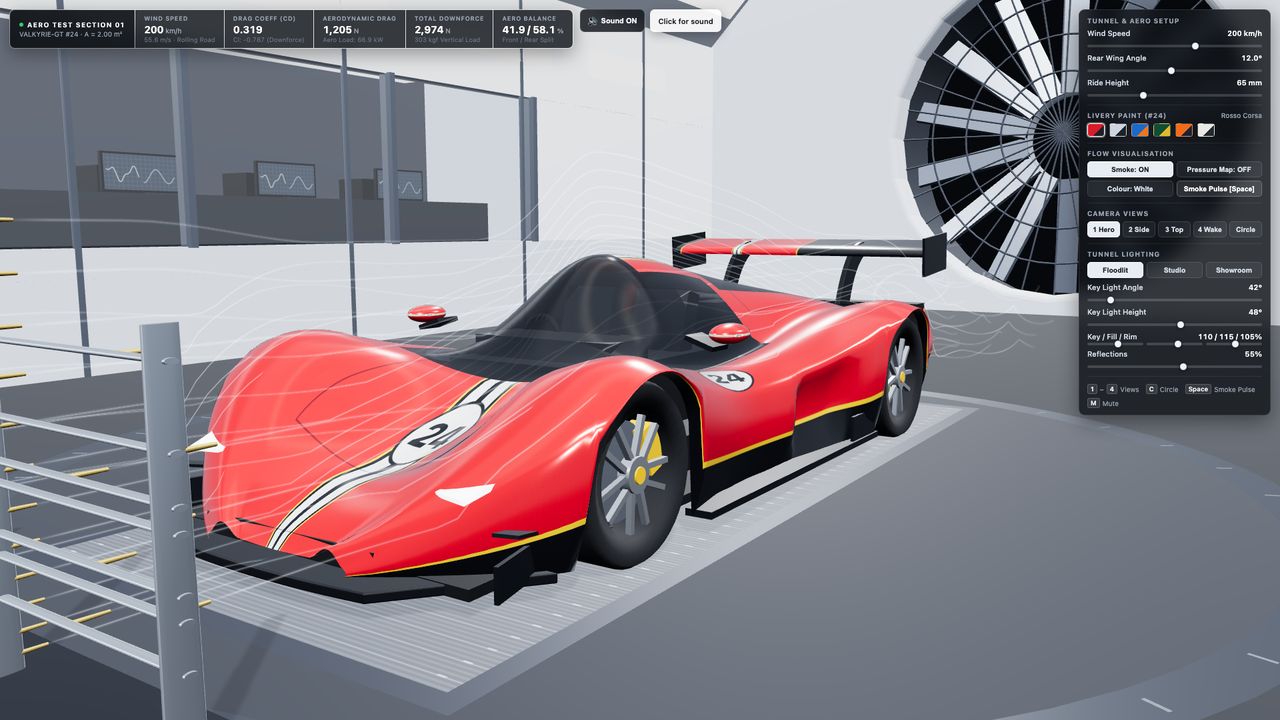
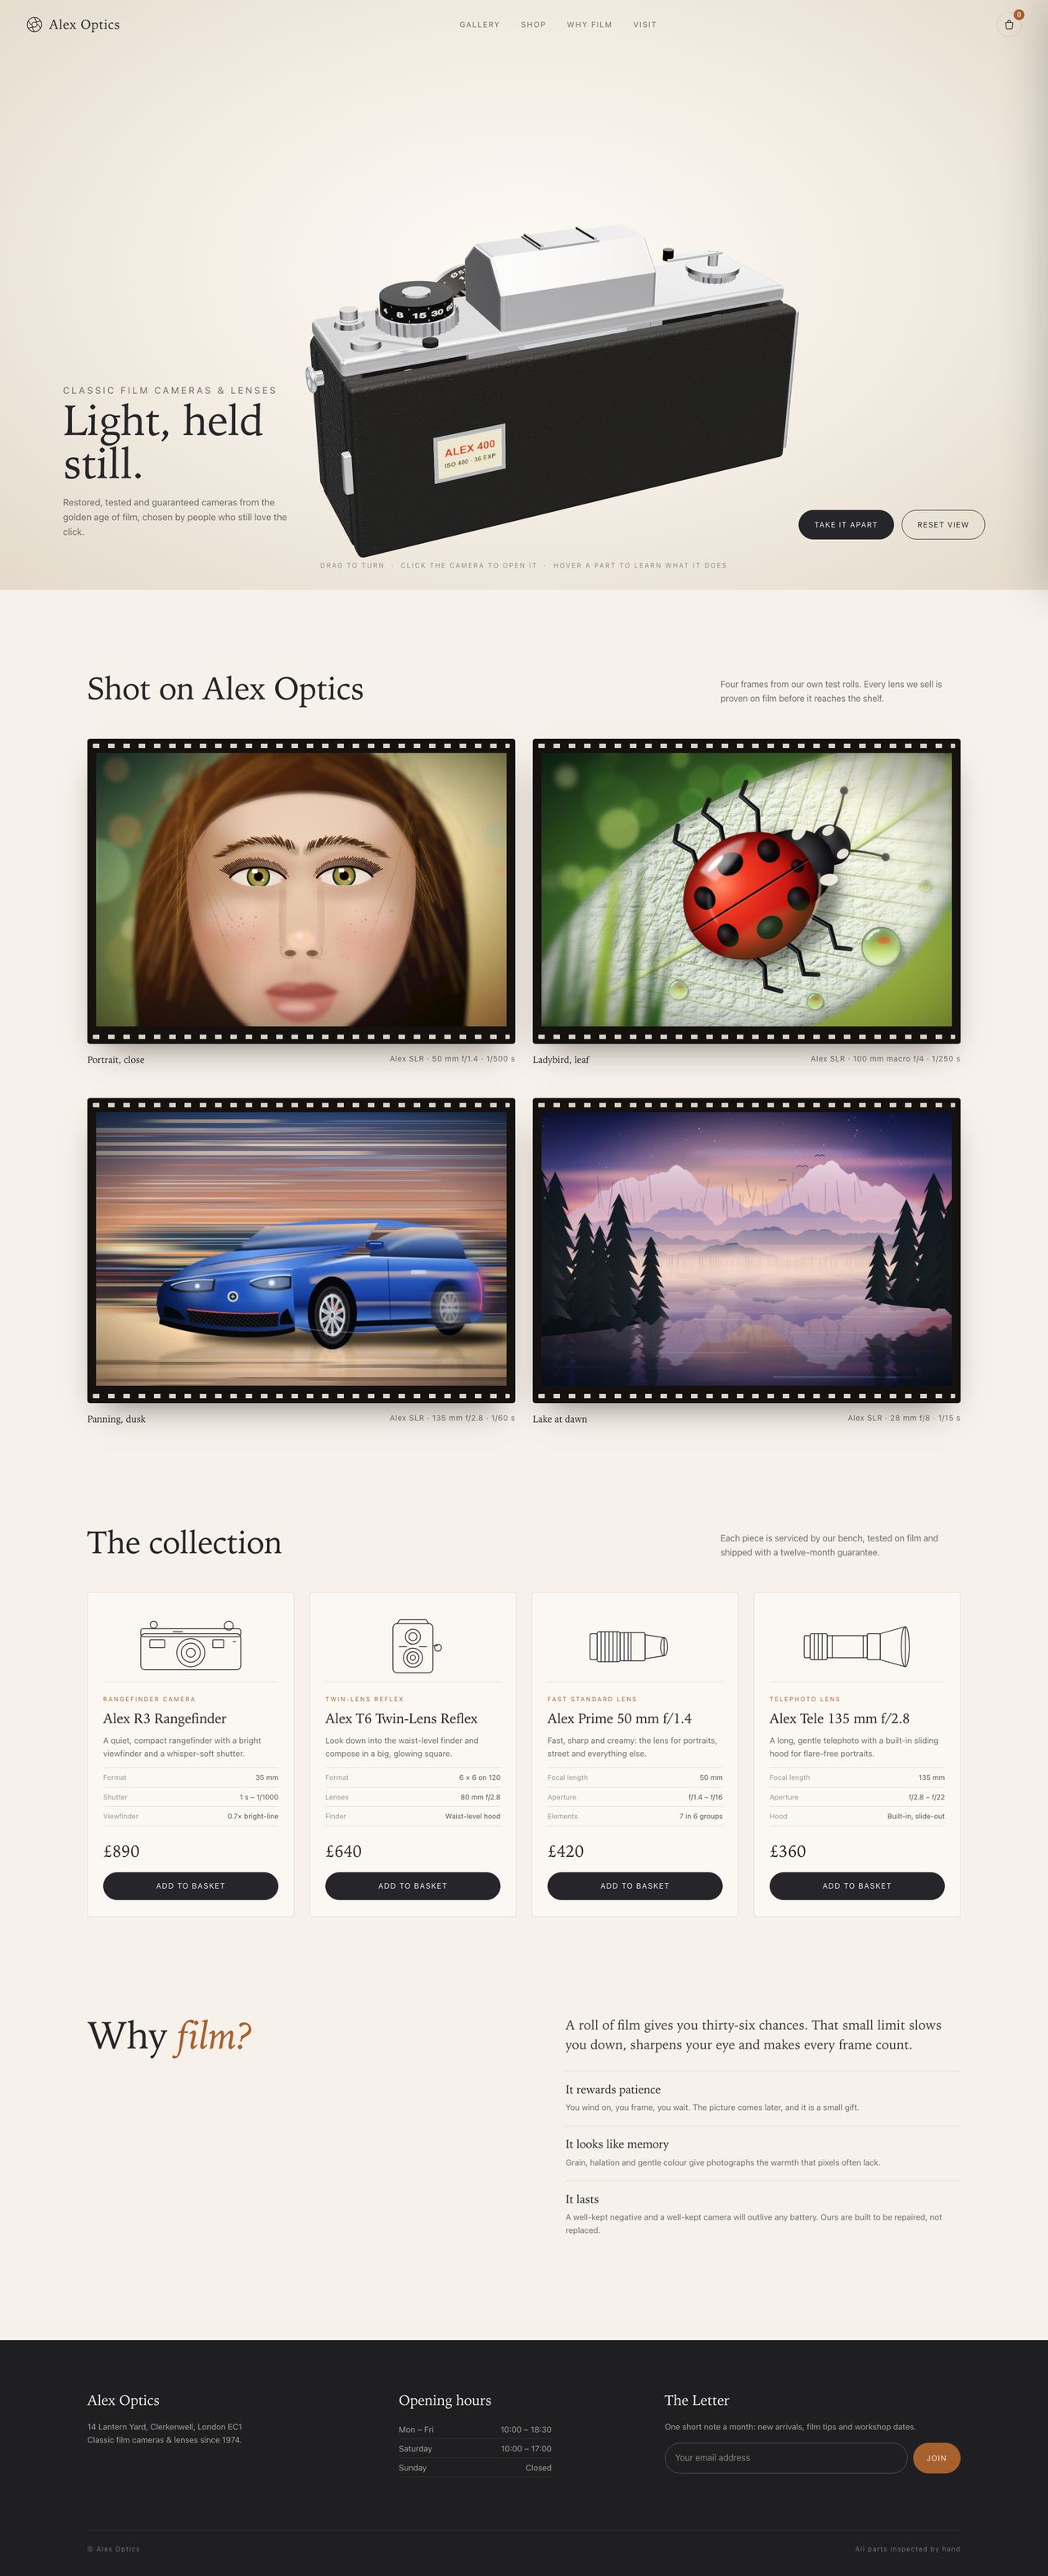
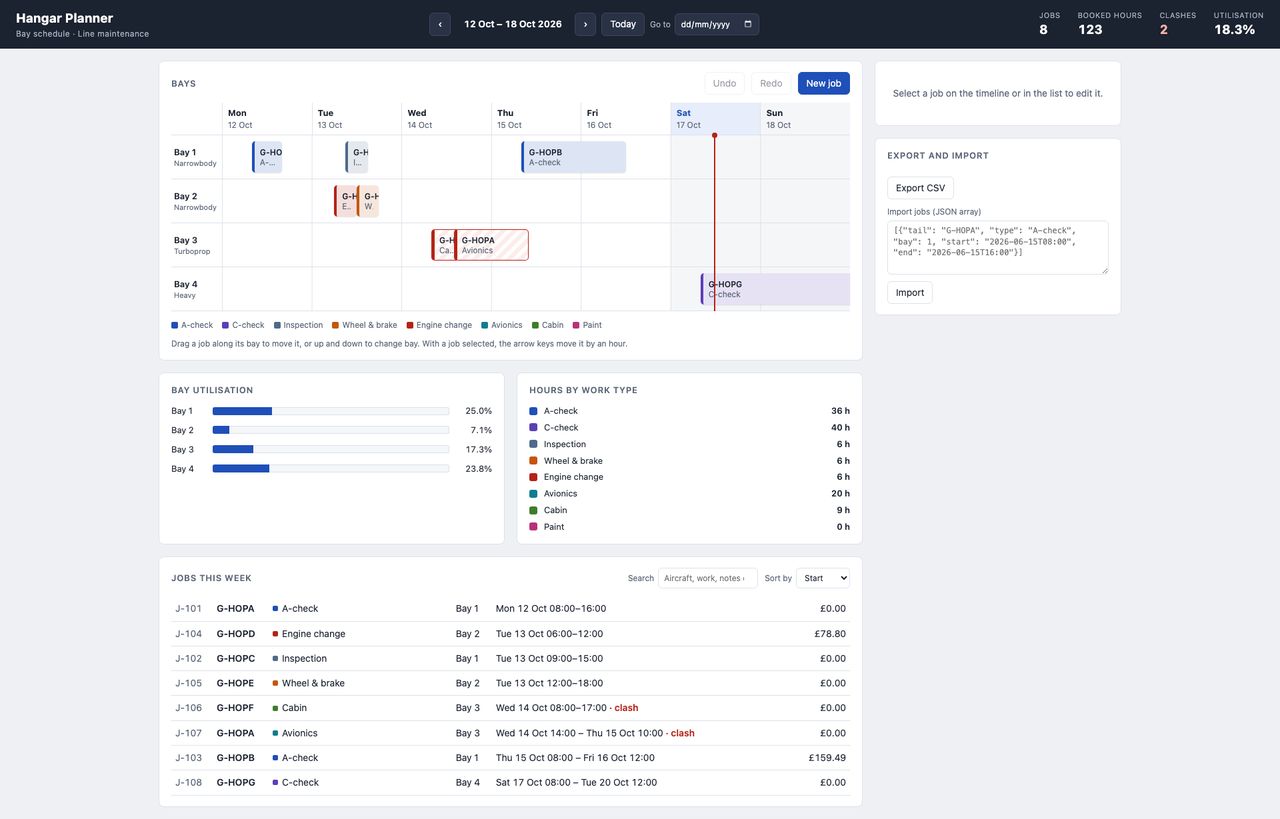
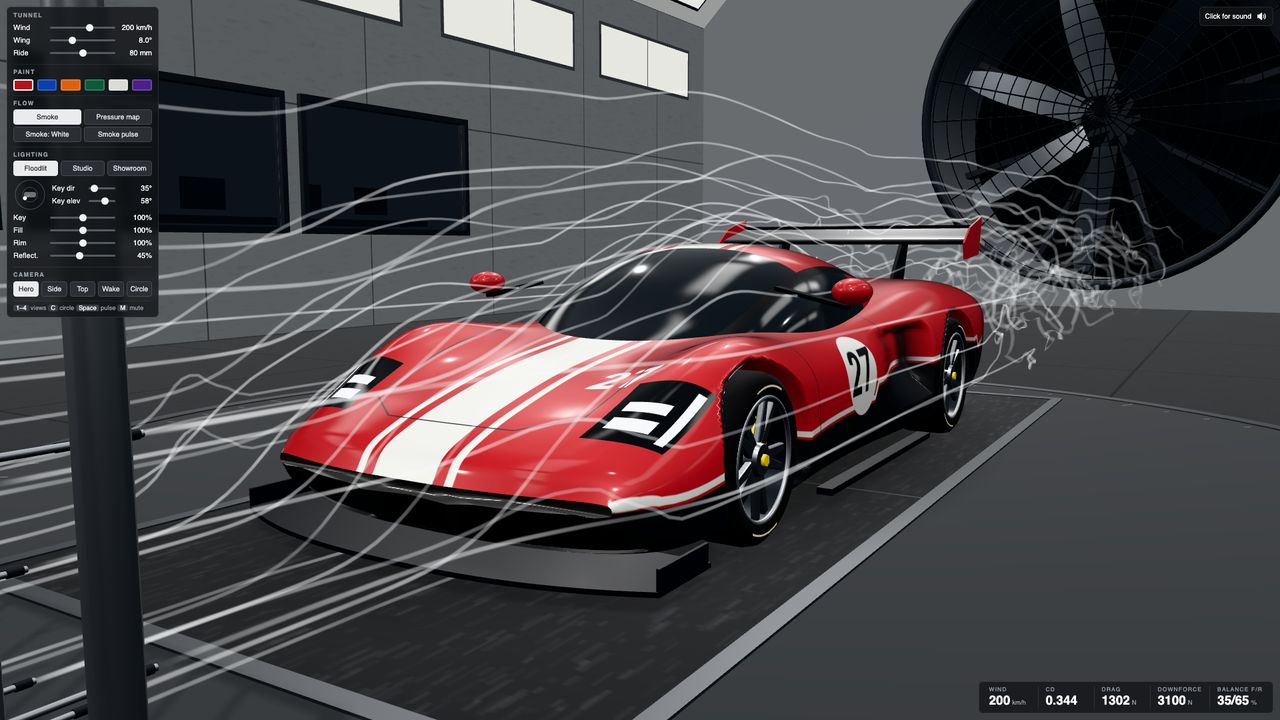
Scoring changed to Quality v3. Pages are now scored out of 100 from a full test of how they work, how they look and how they are built, not from one screenshot, and every result on this site has been rescored. Read more about this change

Same brief. Different models. See what they built.

How AI models do at building interactive web pages: every score, time, token count and cost, with the pages they made.

  • 24models
  • 172pages built
  • 26runs
  • 13videos

Put two models side by side

Pick a provider and a model on each side. You get every page they made next to each other, with the videos they were recorded in.

First model

Second model

Estimated comparison

Exploratory scores across historical test versions. The leaderboard keeps measured editions and tracks separate.

See the whole board
1
claude-fable-5-2effort: highAnthropic
84
2
gpt-6-astraeffort: highOpenAI
≈77
3
kimi-k3.1-proeffort: highMoonshotAI
76
4
75
5
claude-opus-5-5effort: highAnthropic
≈74
050100

≈ is an estimate for a core test that changed or was added after the run, worked out from how the model did on the tests it took. A new run of the model replaces it.

Every video, with its results and files

13 videos, newest first. Each one has the pages that were shown and everything needed to check them.

10 Nov 2026 · 3 runs

Claude Fable 5.2 Tested: 84.46 on the Quality v3 Core Tests, First of 14

Claude Fable 5.2 at high effort through Claude Code, on the five core tests and the wildcard. It scored 84.46 on the five core tests, first of 14 runs on the equivalent core tests, 4.7 points ahead of GPT-6 Astra (79.75, inside the 5-point tie band) and 5.1 ahead of Claude Opus 5.5 (79.33). All six pages were scored, none failed. The five core tests took 2 h 25 m of generation and cost $51.95 at API prices, about $10.39 a test.

  • claude-fable-5-2
  • gpt-6-astra
  • claude-opus-5-5

18 Oct 2026

Should You Wait for Cheaper RAM? 128 GB Local AI Buyer's Guide 2026

Six ways to buy 128 GB for running big AI models at home, from the M5 Max Mac Studio and MacBook Pro to Ryzen AI Max+ 395 and 495 boxes, RTX Spark N1X laptops, the DGX Spark and the RTX 5090 and RTX PRO 6000 route. Prices checked on 18 October 2026, llama.cpp speeds I measured on my own M5 Max (gpt-oss-120b at 79.2 tokens a second), and what is coming soon for anyone deciding whether to buy now or wait. No benchmark runs in this one.

17 Oct 2026 · 6 runs

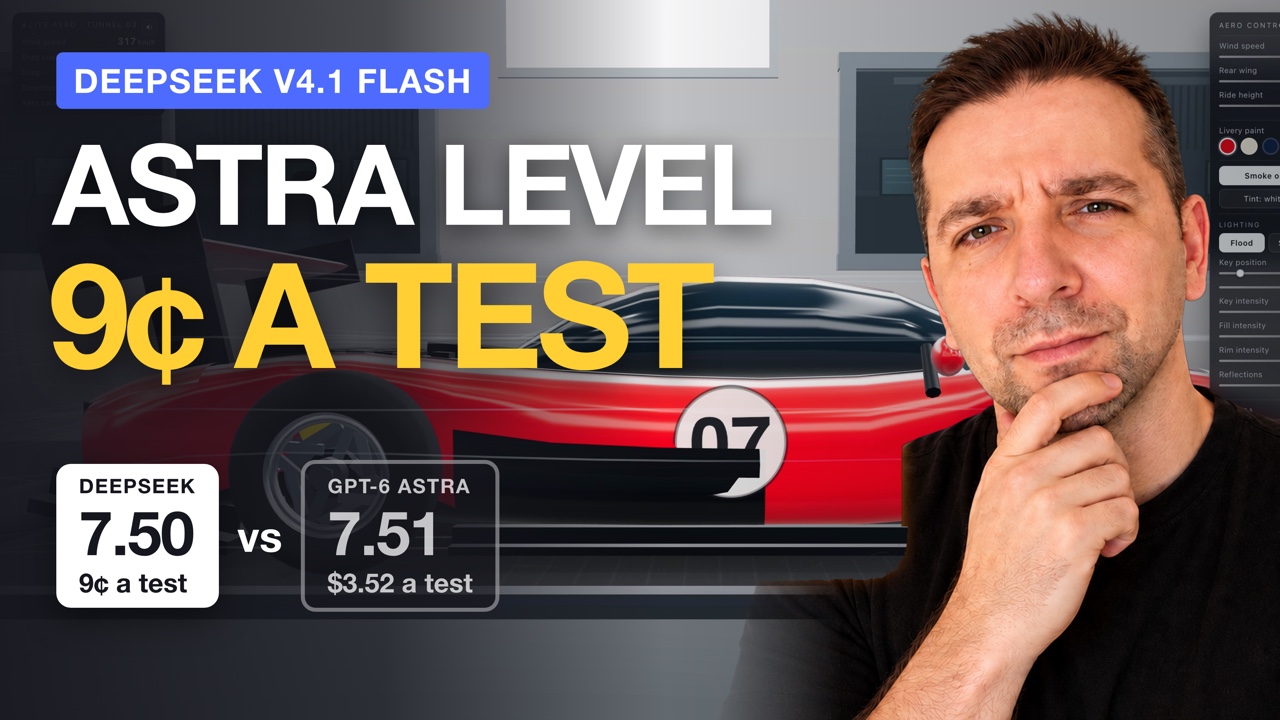
DeepSeek V4.1 Flash 1017 vs GPT-6 Astra: Same Score for 9 Cents a Test

DeepSeek updated V4.1 Flash on 17 October, so I ran the 1017 snapshot through OpenRouter at high effort on release day. It scored 7.50 on eight tests, second of 18 models, 0.01 behind GPT-6 Astra and ahead of Opus 5.5 and Sonnet 5.5. All eight tests cost 71 cents on my OpenRouter bill, about 9 cents a test, against about $3.77 for Astra and $5.18 for Opus on the same tests. Visually, Opus and Sonnet are still ahead.

  • deepseek/deepseek-v4.1-flash-1017
  • claude-haiku-5-5
  • claude-sonnet-5-5
  • gpt-6-astra
  • claude-opus-5-5
  • gpt-6-luna

14 Oct 2026 · 4 runs

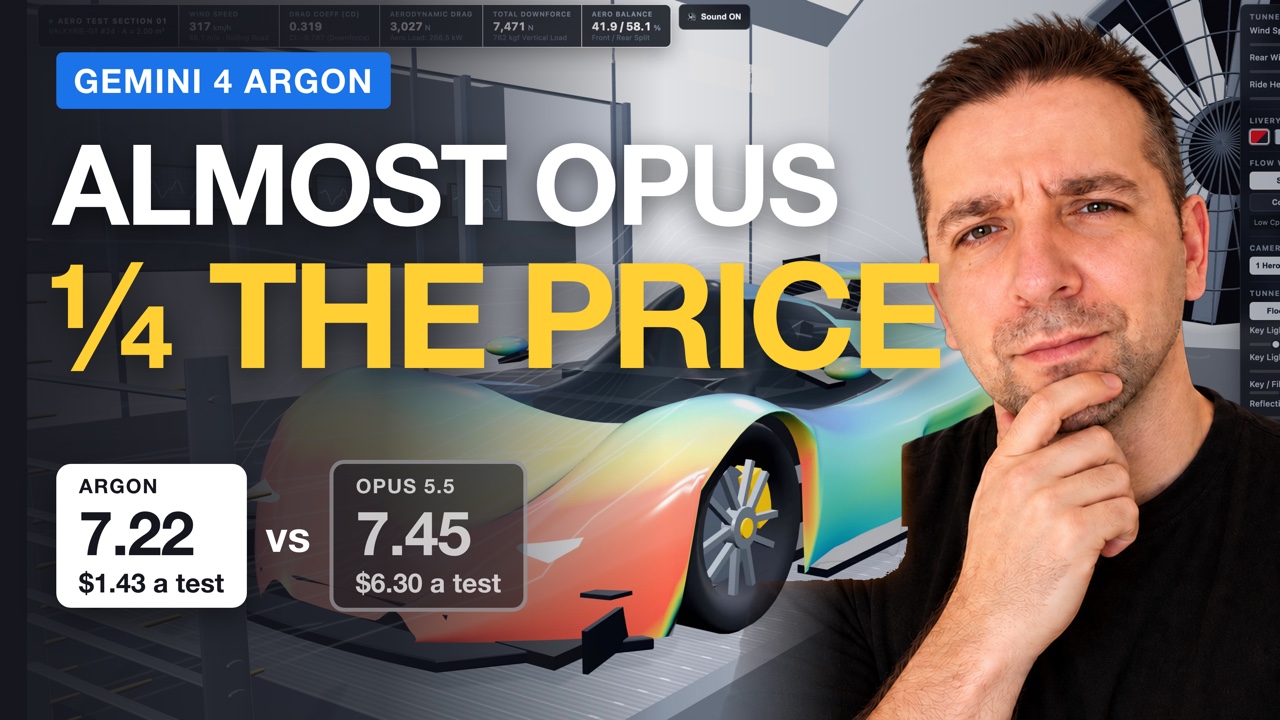
Gemini 4 Argon Tested: Almost Opus 5.5 for a Quarter of the Price

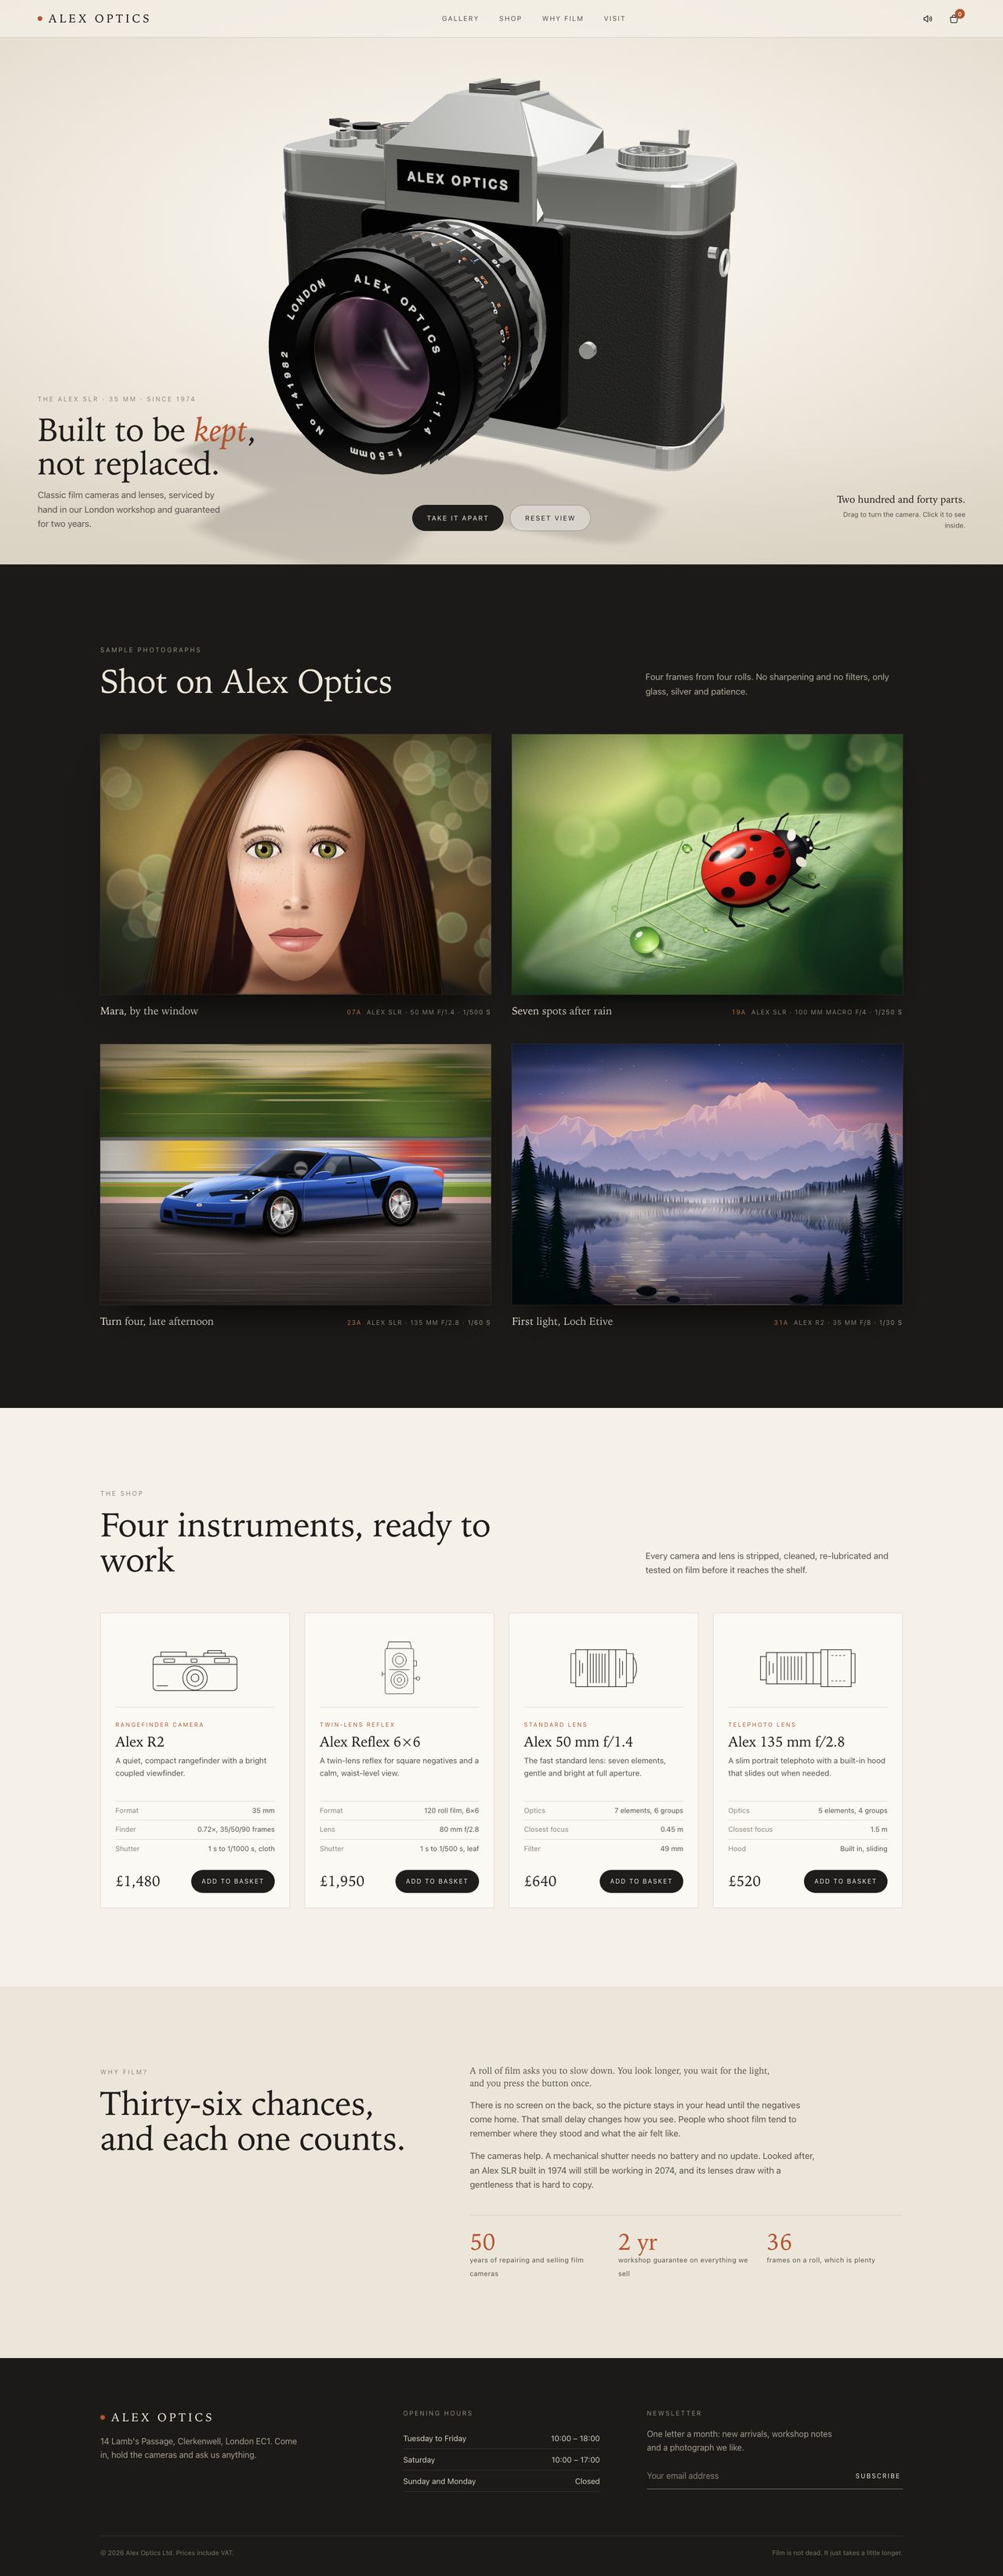
Google opened Gemini 4 Argon to everyone, so I ran it through the Gemini API at high effort. On the four tests it finished it scored 7.22, third of 17 models, behind Opus 5.5 (7.45) and GPT-6 Astra (7.36). It wrote about half as many output tokens as Opus, so each test cost about $1.43 against Opus's $6.30. Two of its six tests did not finish: Google's stream cut off on Alex Optics, and the wildcard hit my API spending cap.

  • gemini-4-argon
  • claude-sonnet-5-5
  • gpt-6-astra
  • claude-opus-5-5

12 Oct 2026 · 3 runs

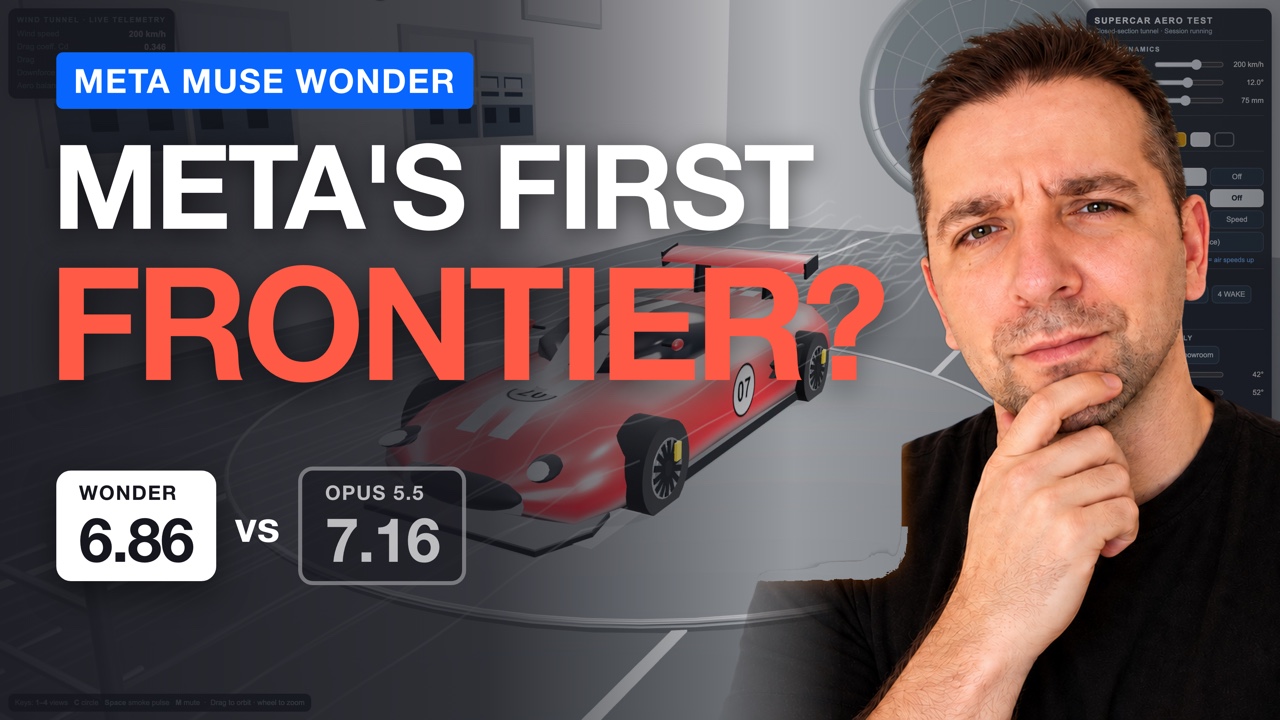
Meta Muse Wonder Tested: Is Meta Finally Frontier?

Meta's first frontier model, tested on launch day at maximum effort. On the five tests it finished, Muse Wonder scored 6.86, fourth of 16 models, behind GPT-6 Astra, Opus 5.5 and Sonnet 5.5. It costs the same per token as Opus 5.5 but wrote far fewer tokens, so each test cost about $2.17 against Opus's $5.89. It scored below Opus on four of the five.

  • meta/muse-wonder
  • gpt-6-astra
  • claude-opus-5-5

10 Oct 2026

I'm Building an AI Agent Office That Can Run 100% Local (Ep. 1)

Episode one of Model Office, an office where AI models live and work. Ten colleagues, each on its own model, from Claude, Gemini and OpenRouter to a local model through LM Studio or Ollama. The three office modes, whether they can fight (scripted, for now), and the single commit that replaced six of the cast. No benchmark runs in this one.