gpt-6-astraeffort: highOpenAI · 3 Oct 2026
7.5 / 10Quality v1 · 8/8 pages
Time3h 31m
Output tokens322k
Cost≈$31.69API price, est.
Home › Videos › Claude Opus 5.5 vs GPT-6 Astra — Visual Forge Benchmark
3 Oct 2026 · 2 runs · 2 models
Claude Opus 5.5 against GPT-6 Astra on interactive app and game tests. Every score, time, token count and cost, with the pages each model built.
The same scores as the leaderboard: a test that failed is left out of its run's score, not counted as zero. Time, tokens and cost cover each whole run, wildcards included.
Quality v1 over measured non-wildcard pages. Different workloads: browse the outputs and coverage before comparing models.
Quality v1 against full-run tokens. Different workloads and hardware affect this comparison.
Output tokens include the model's thinking. Like the time, tokens and cost table, it counts every test the model took, wildcards included. The score axis is zoomed to the data.
Quality v1 against full-run time. Different workloads and hardware affect this comparison.
Time is how long the model took to answer, added up over its tests; judging is not counted. Like the time, tokens and cost table, it counts every test the model took, wildcards included. The score axis is zoomed to the data.
One row per model, one column per test and per scoring criterion.
| By test | By what the judges scored | |||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Model | Aero Lab | Jet Odyssey | Blast Island | Launch Day | Alex Optics | Afterburner | Hangar Ops | Hangar Planner | Rotor Rampage | Working behaviour | Visual quality | Engineering quality | Usability / accessibility | |
| gpt-6-astraeffort: high | 7.8 | 7.6 | 7.0 | 7.1 | 7.8 | 7.8 | — | 7.3 | 7.8 | 8.2 | 8.2 | 6.7 | 6.3 | |
| claude-opus-5-5effort: high | 7.7 | 7.0 | 7.5 | 7.7 | 6.0 | 8.3 | 7.4 | — | 7.9 | 8.0 | 8.0 | 6.9 | 6.2 | |
What each model used across all its tests, wildcards included.
| Model | Tests | Time | Output tokens | Speed | Cost | Subscription used |
|---|---|---|---|---|---|---|
| gpt-6-astraeffort: highOpenAI | 9 | 3h 31m | 322k75k of it thinking | 25.4 tok/s | ≈$31.69API price, est. | — |
| claude-opus-5-5effort: highAnthropic | 8 | 3h 29m | 1.30M753k of it thinking | 103.0 tok/s | $36.60API price | 5-hour window not comparable7-day window +2 pts |
Read from the account's usage window in whole percentage points, so a short run can show 0 points. It counts everything the account did in that time, not only this run.
Every run behind the numbers. Scores name their comparison basis.
OpenAI · 7.5 / 10 · Quality v1 · 8/8 pages · 3h 31m · ≈$31.69
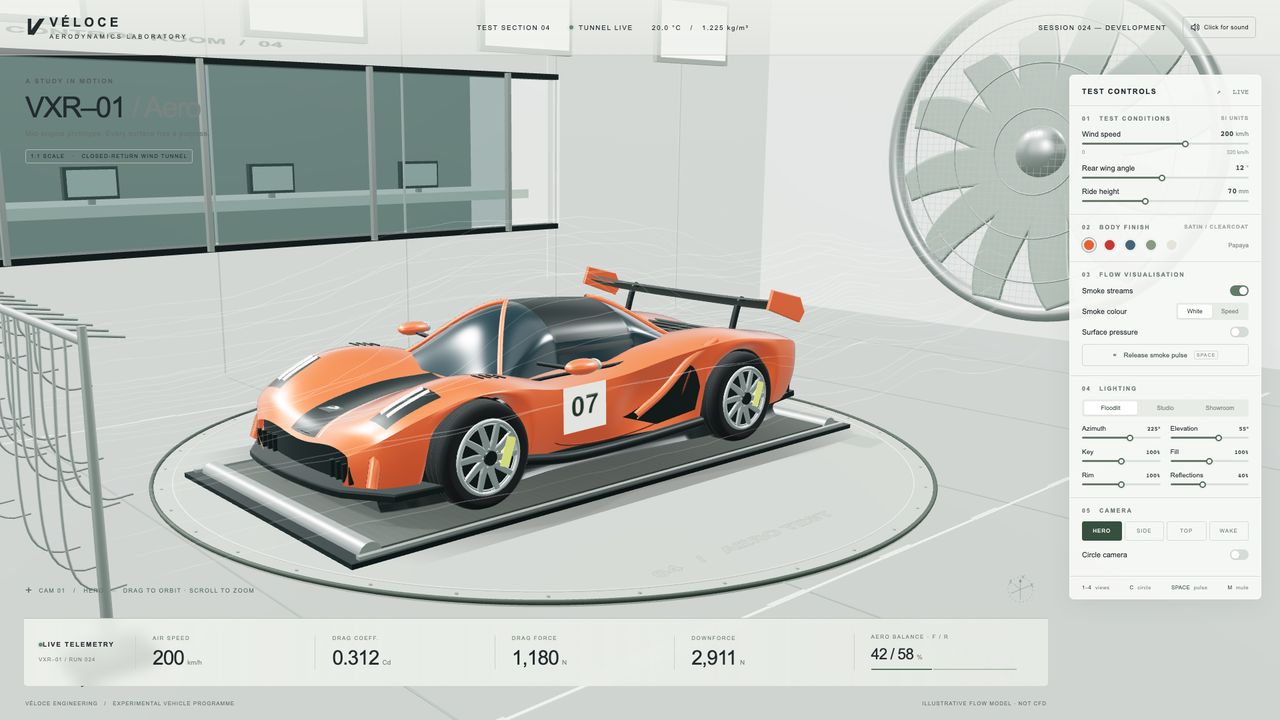 7.8
6.0/10 · engineering-1 · claude-code/claude-opus-5-5 (engineering-1 rubric)
Different rubrics; these values are historical, not a score change.
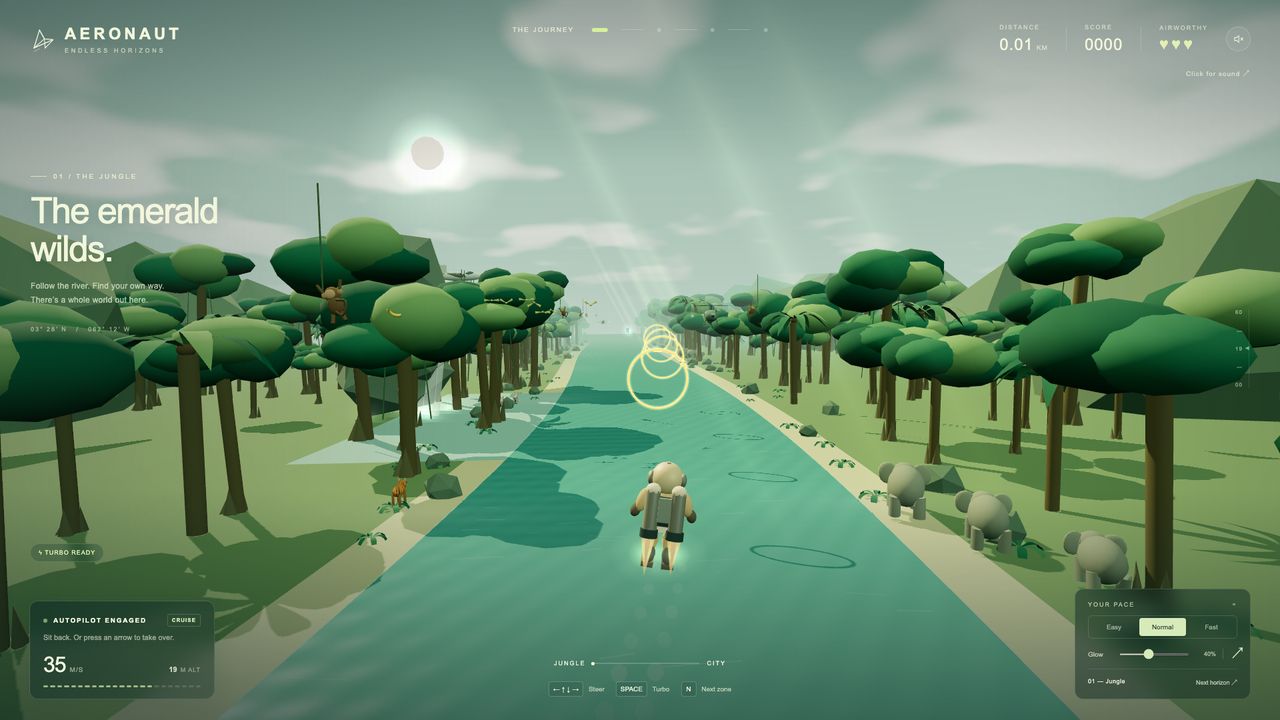 7.6
6.6/10 · engineering-1 · claude-code/claude-opus-5-5 (engineering-1 rubric)
Different rubrics; these values are historical, not a score change.
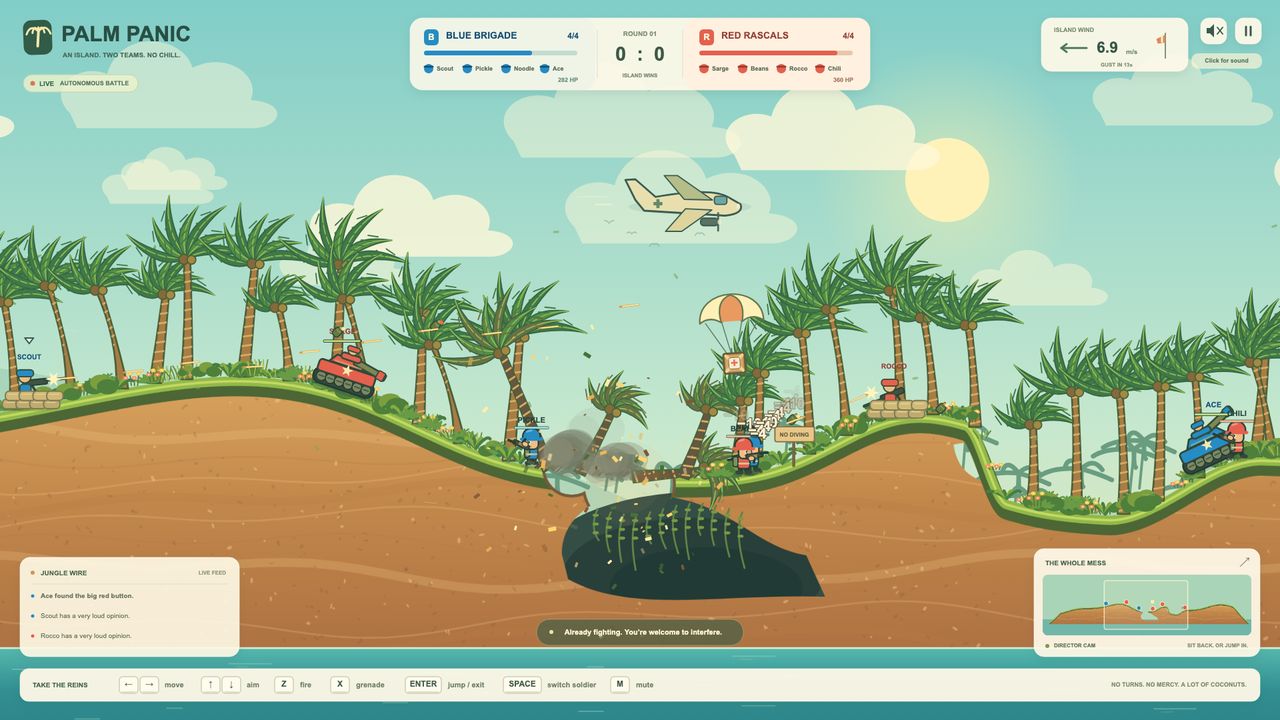 7.0
6.7/10 · engineering-1 · claude-code/claude-opus-5-5 (engineering-1 rubric)
Different rubrics; these values are historical, not a score change.
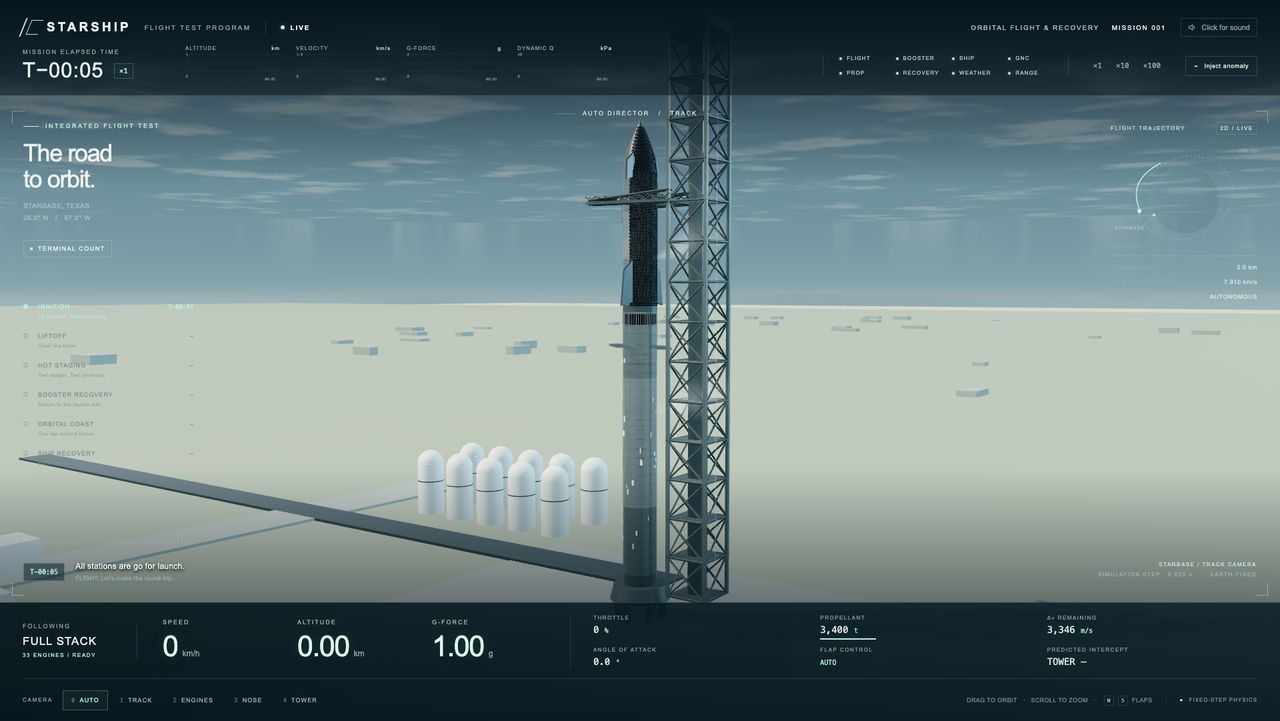 7.1
5.8/10 · engineering-1 · claude-code/claude-opus-5-5 (engineering-1 rubric)
Different rubrics; these values are historical, not a score change.
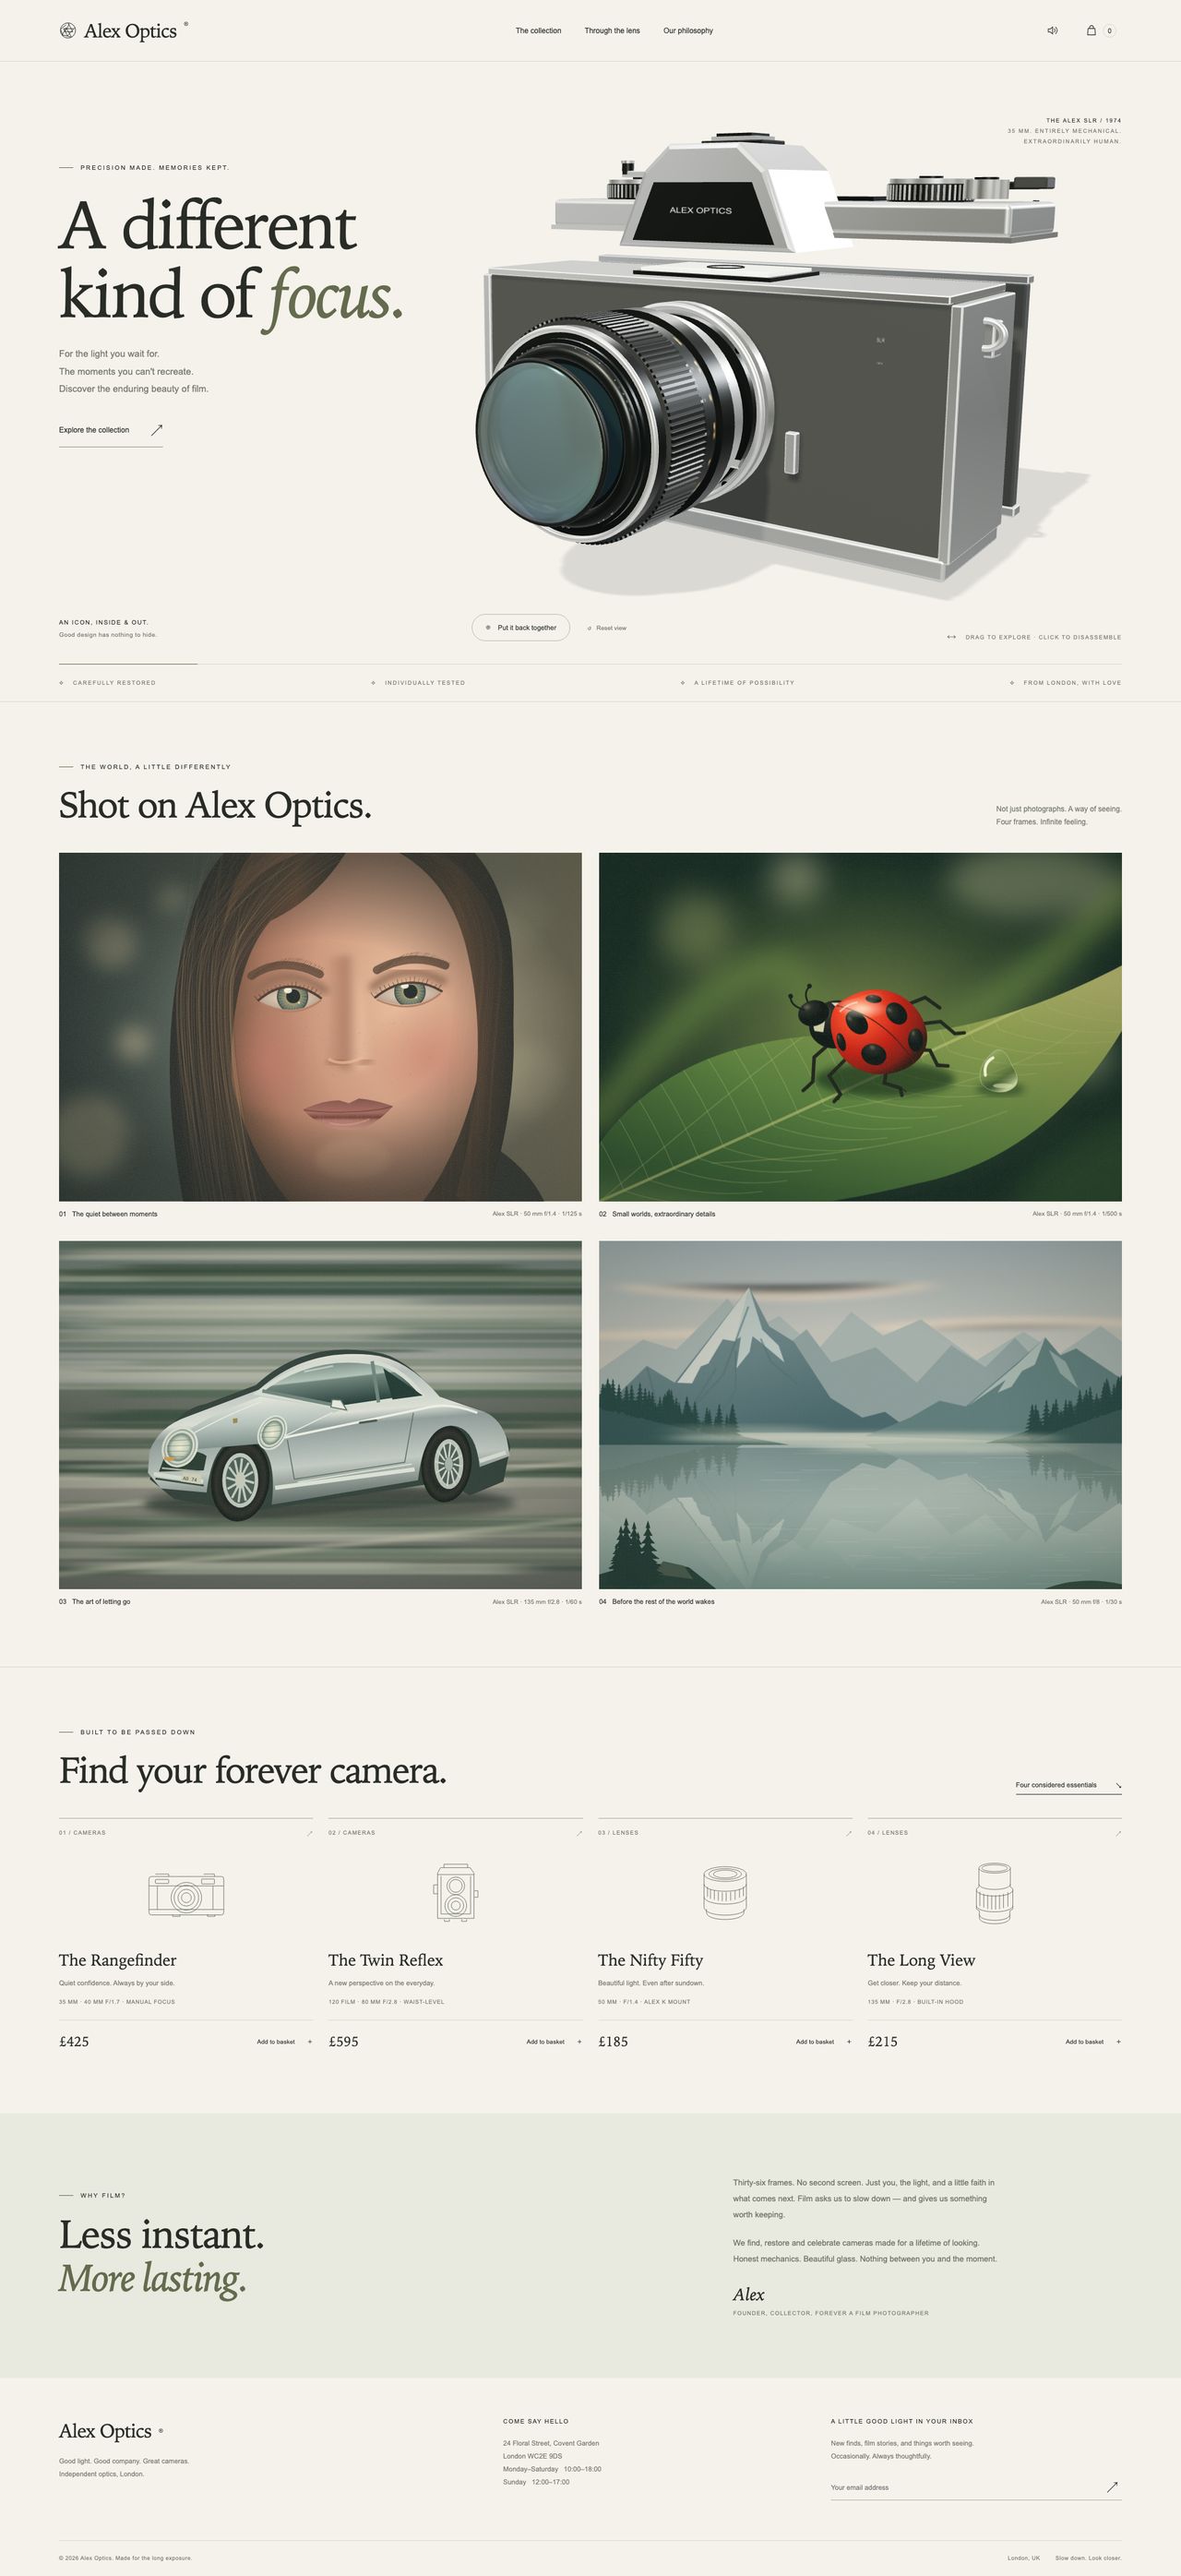 7.8
7.5/10 · engineering-1 · claude-code/claude-opus-5-5 (engineering-1 rubric)
Different rubrics; these values are historical, not a score change.
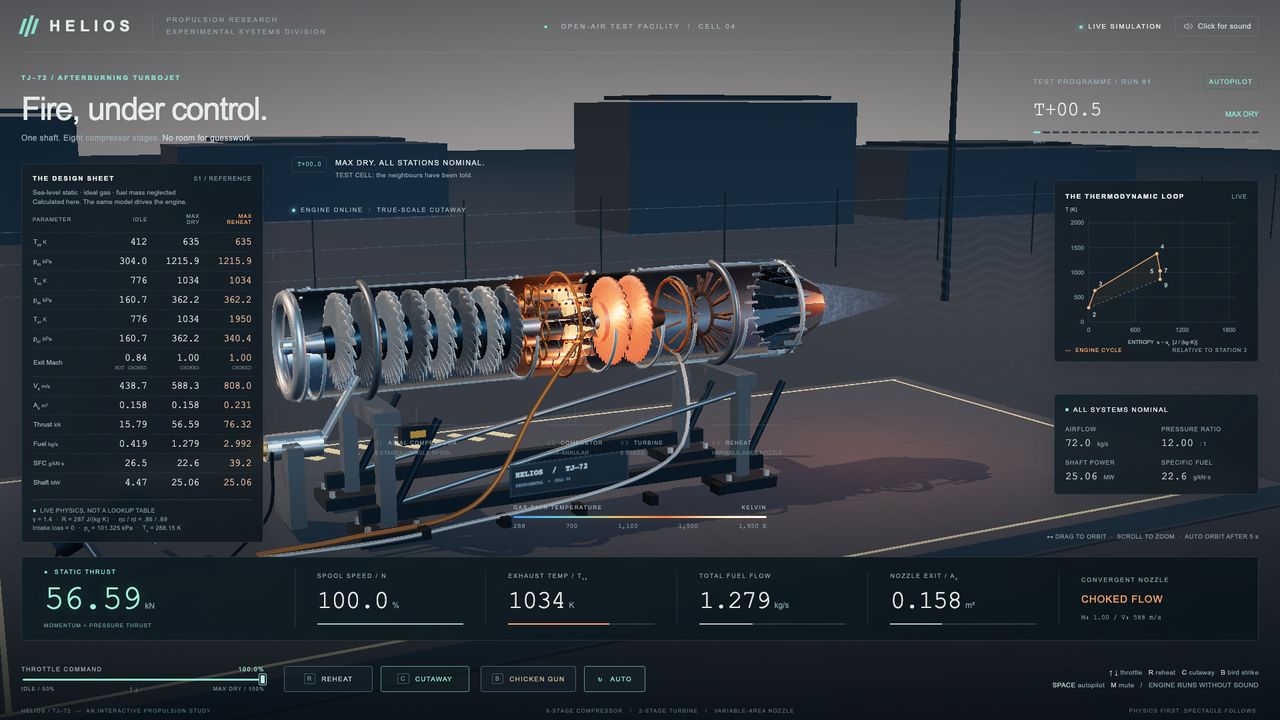 7.8
8.2/10 · engineering-1 · claude-code/claude-opus-5-5 (engineering-1 rubric)
Different rubrics; these values are historical, not a score change.
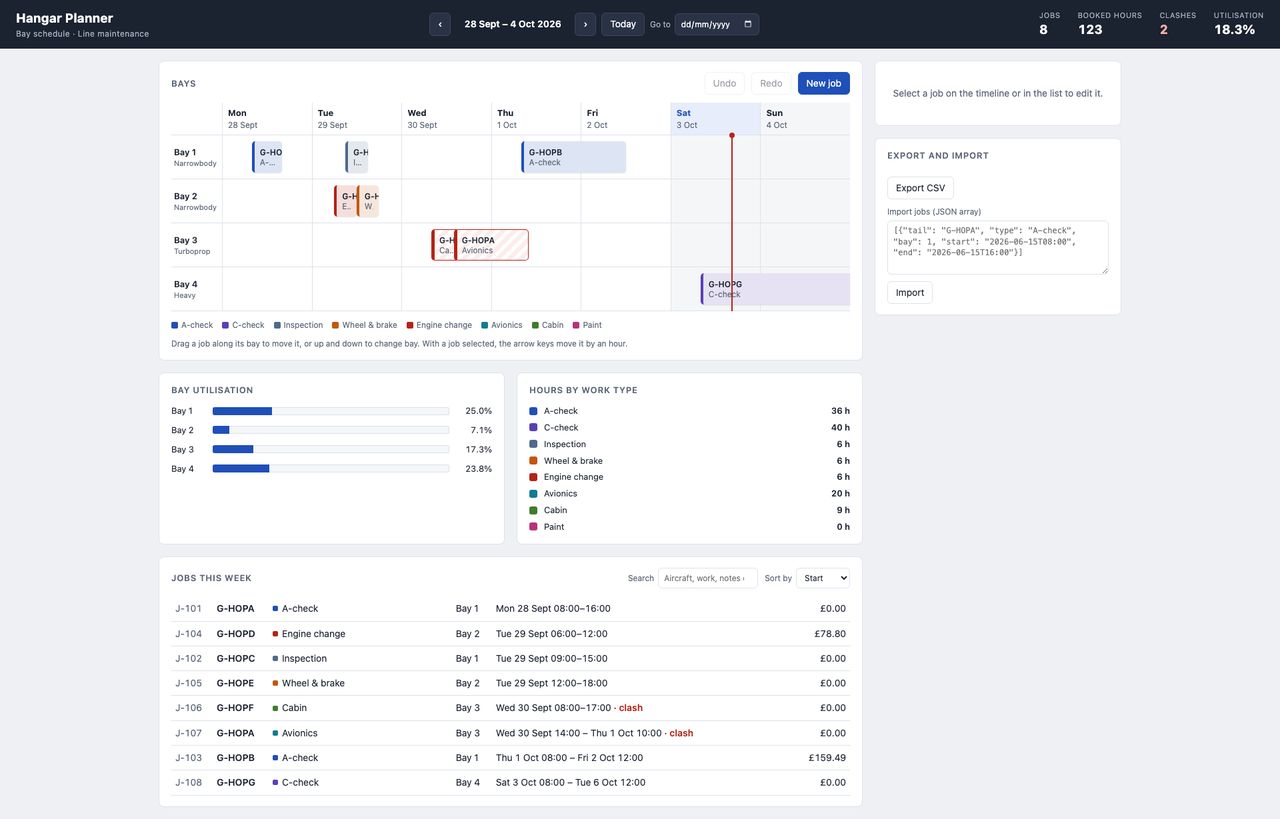 7.3
9.0/10 · engineering-1 · claude-code/claude-opus-5-5 (engineering-1 rubric)
Different rubrics; these values are historical, not a score change.
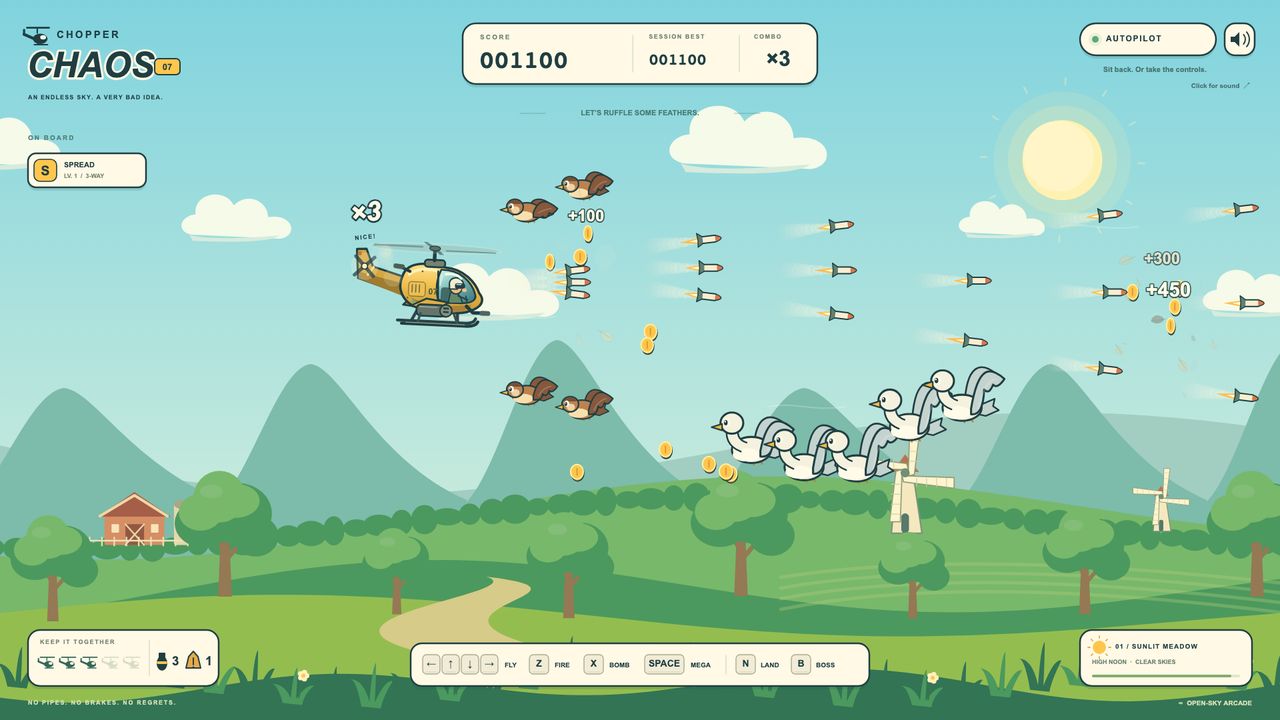 7.8
7.2/10 · engineering-1 · claude-code/claude-opus-5-5 (engineering-1 rubric)
Different rubrics; these values are historical, not a score change.
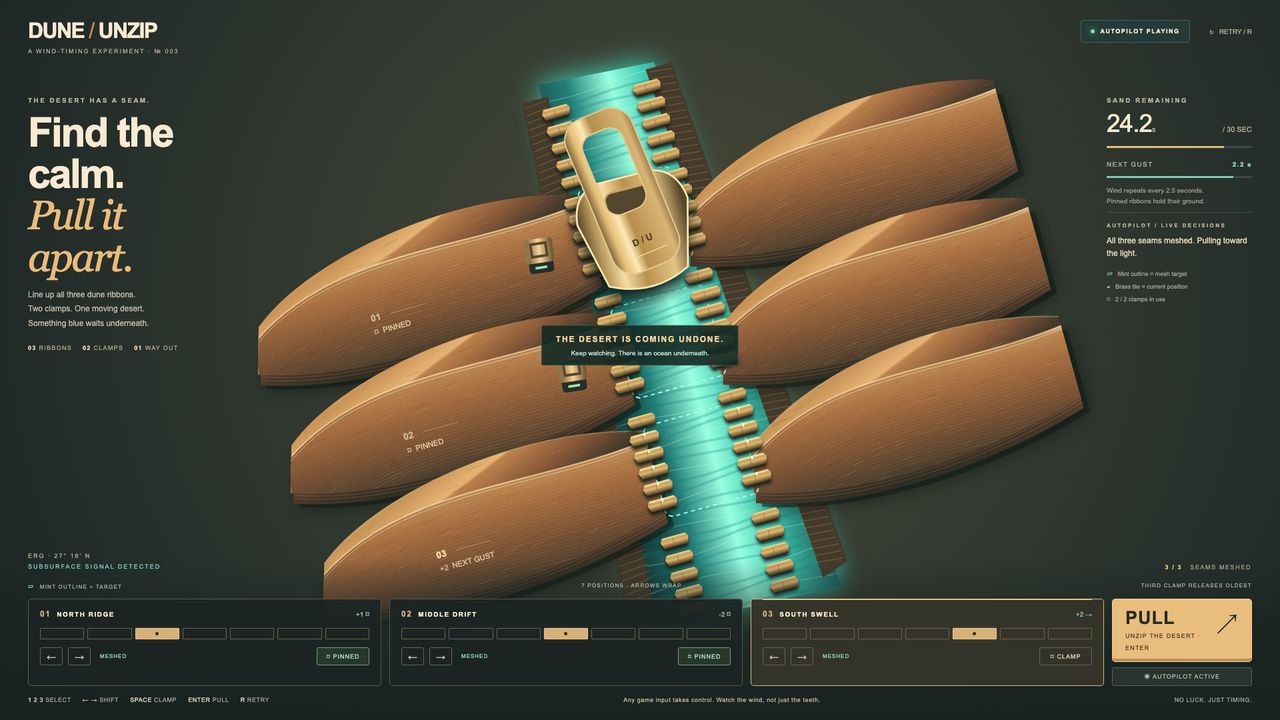 7.4
6.9/10 · engineering-1 · claude-code/claude-opus-5-5 (engineering-1 rubric)
Different rubrics; these values are historical, not a score change.
Anthropic · 7.4 / 10 · Quality v1 · 8/8 pages · 3h 29m · $36.60
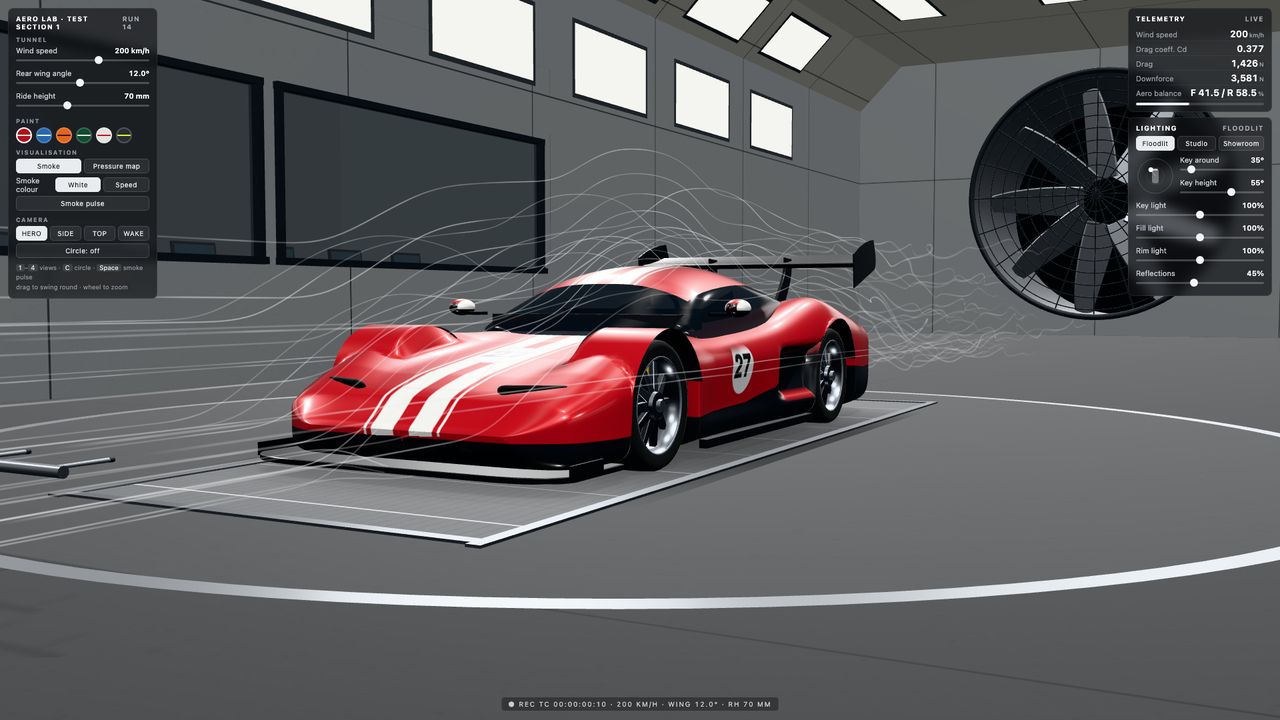 7.7
7.6/10 · engineering-1 · claude-code/claude-opus-5-5 (engineering-1 rubric)
Different rubrics; these values are historical, not a score change.
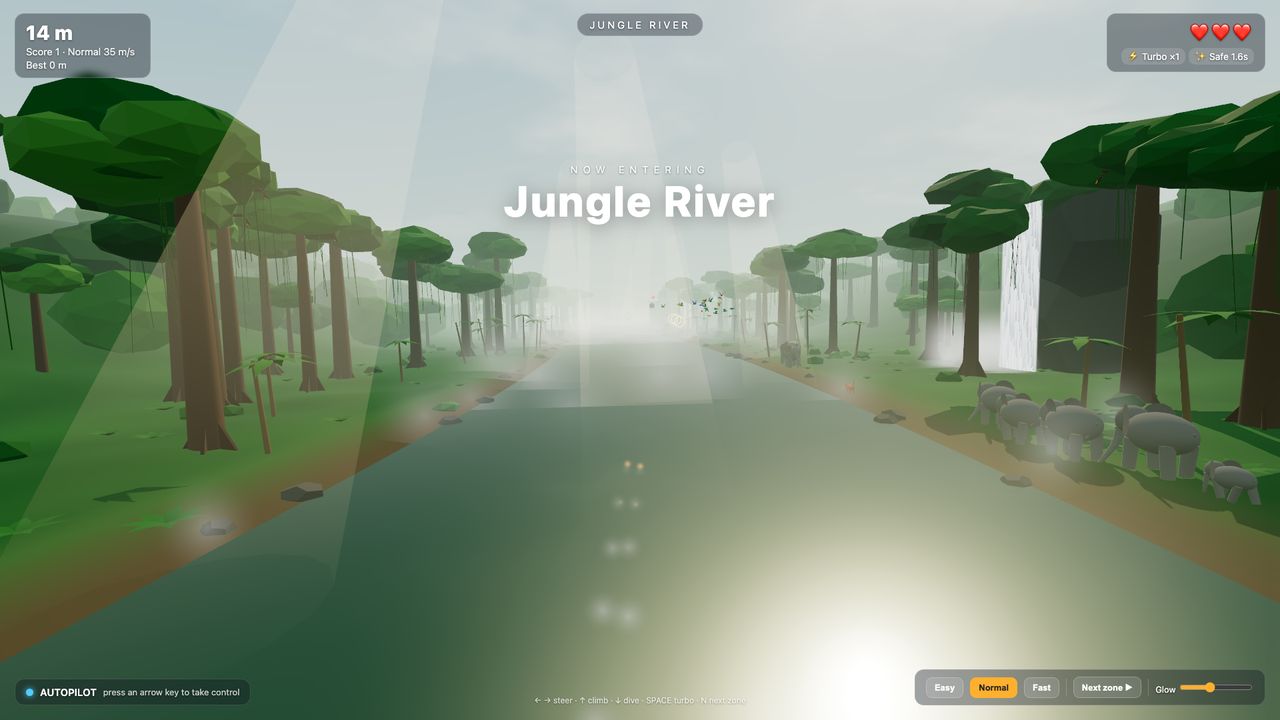 7.0
6.8/10 · engineering-1 · claude-code/claude-opus-5-5 (engineering-1 rubric)
Different rubrics; these values are historical, not a score change.
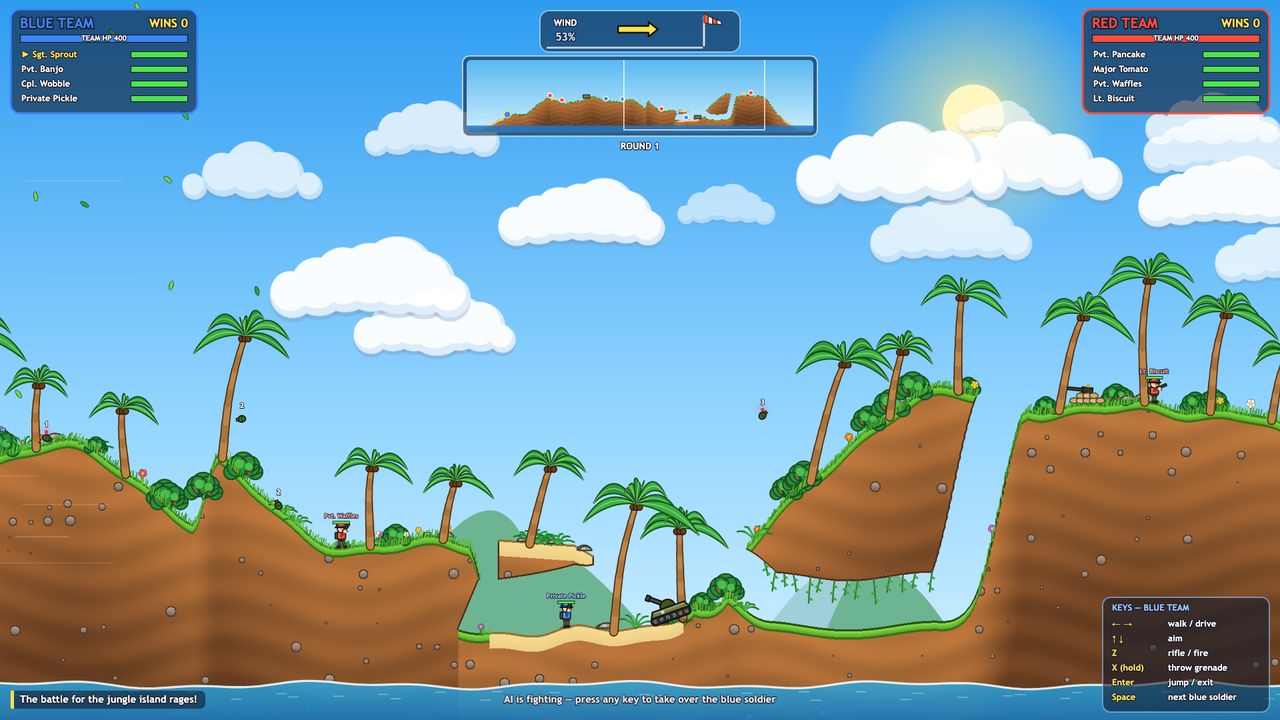 7.5
7.2/10 · engineering-1 · claude-code/claude-opus-5-5 (engineering-1 rubric)
Different rubrics; these values are historical, not a score change.
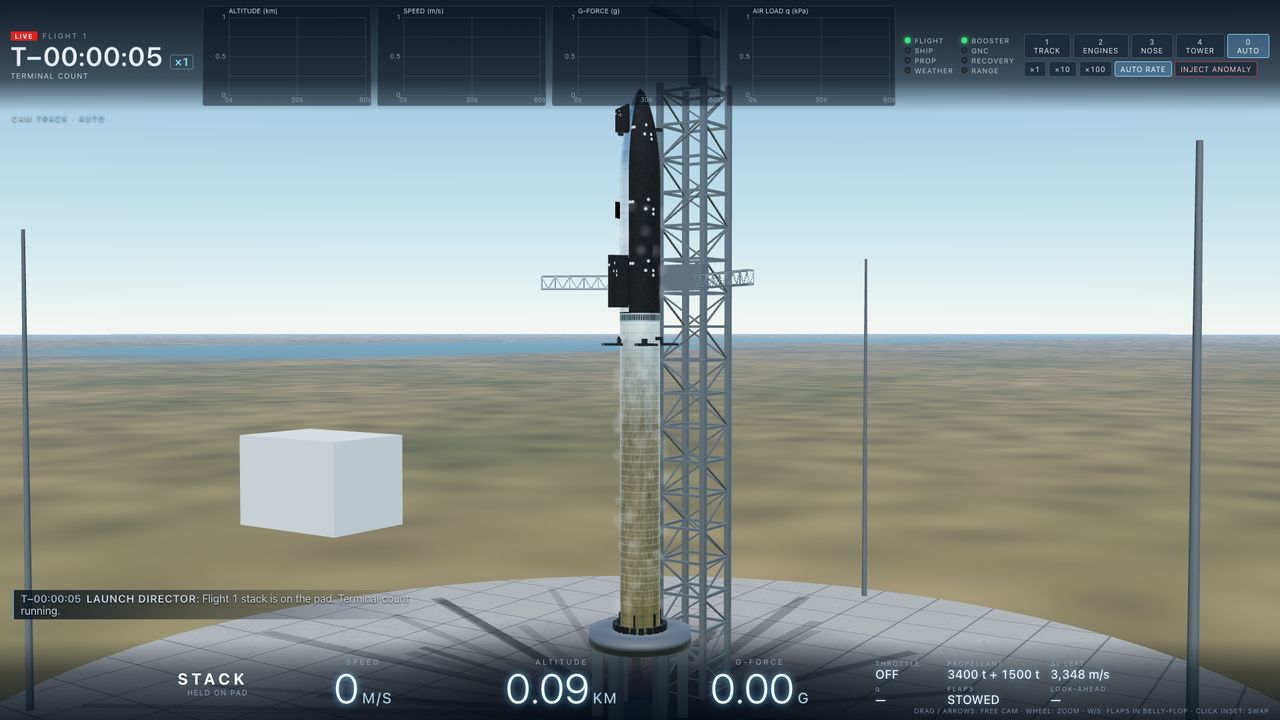 7.7
6.7/10 · engineering-1 · claude-code/claude-opus-5-5 (engineering-1 rubric)
Different rubrics; these values are historical, not a score change.
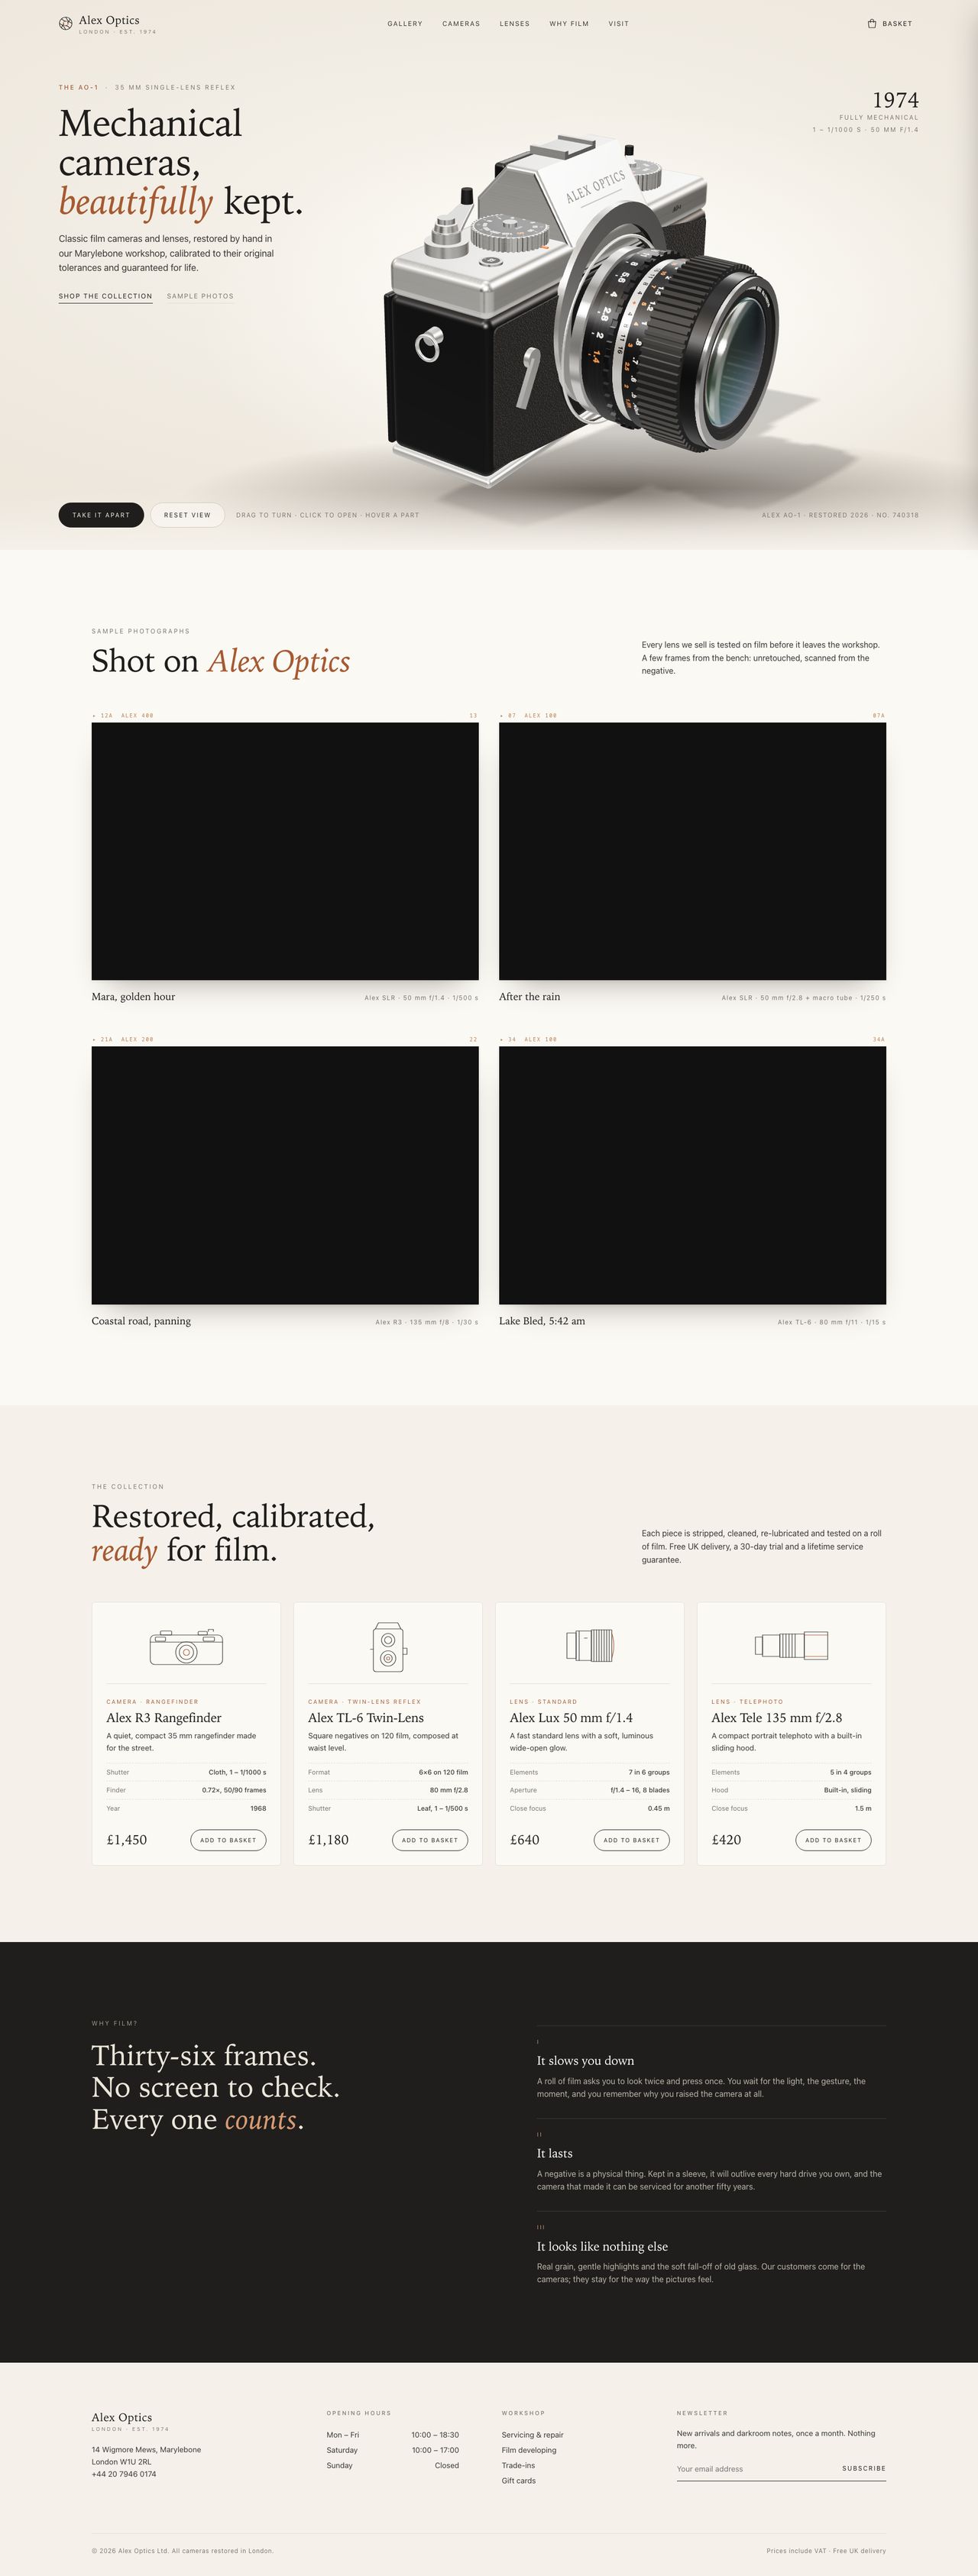 6.0
5.6/10 · engineering-1 · claude-code/claude-sonnet-5-5 (engineering-1 rubric)
Different rubrics; these values are historical, not a score change.
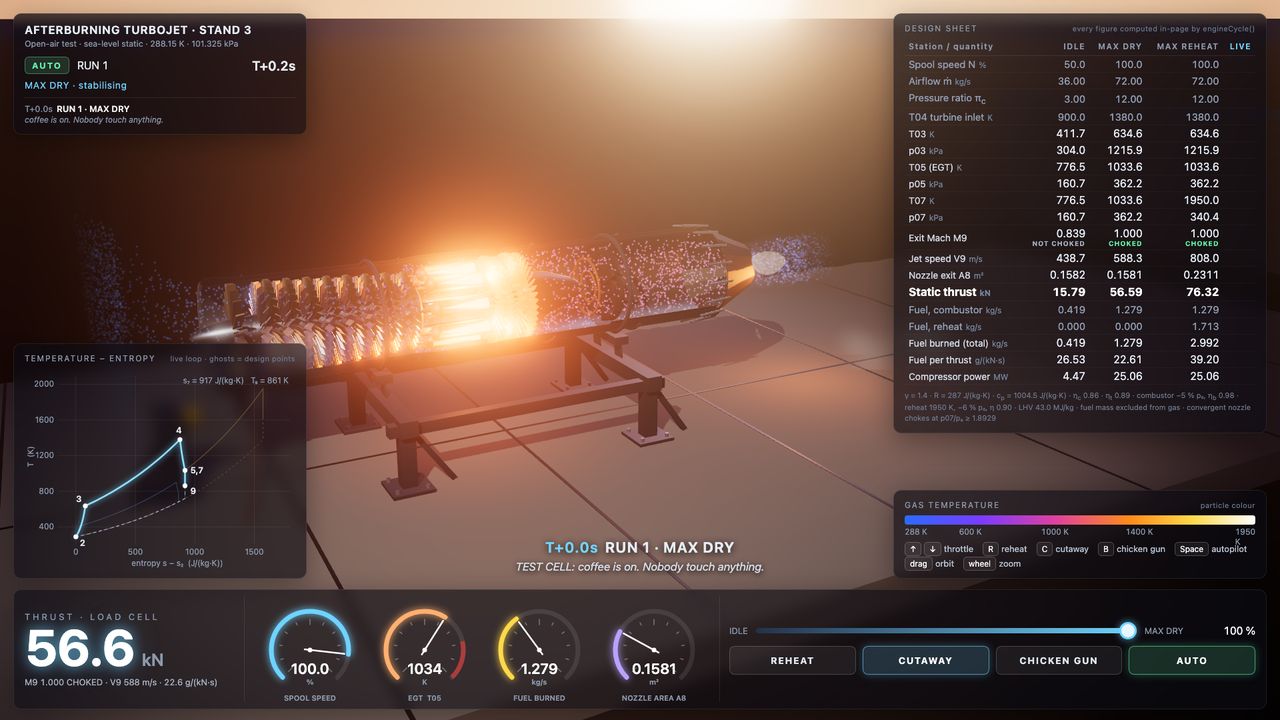 8.3
8.5/10 · engineering-1 · claude-code/claude-opus-5-5 (engineering-1 rubric)
Different rubrics; these values are historical, not a score change.
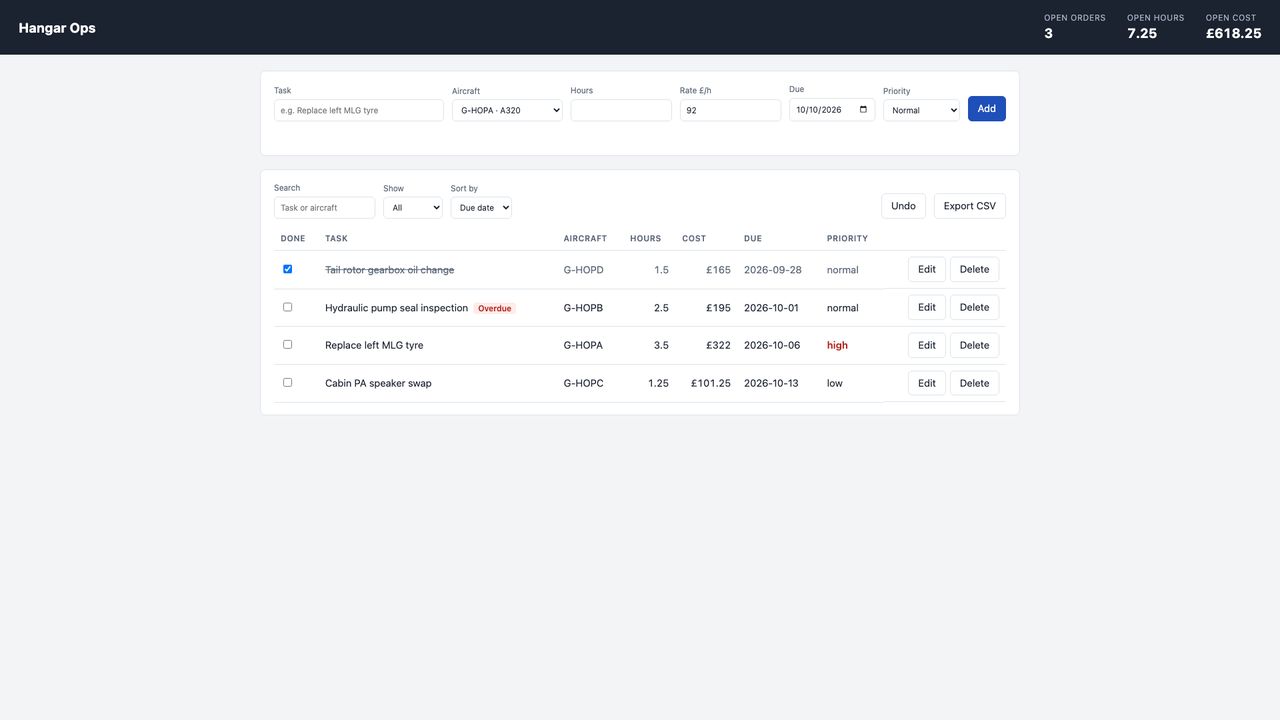 7.4
8.6/10 · engineering-1 · claude-code/claude-opus-5-5 (engineering-1 rubric)
Different rubrics; these values are historical, not a score change.
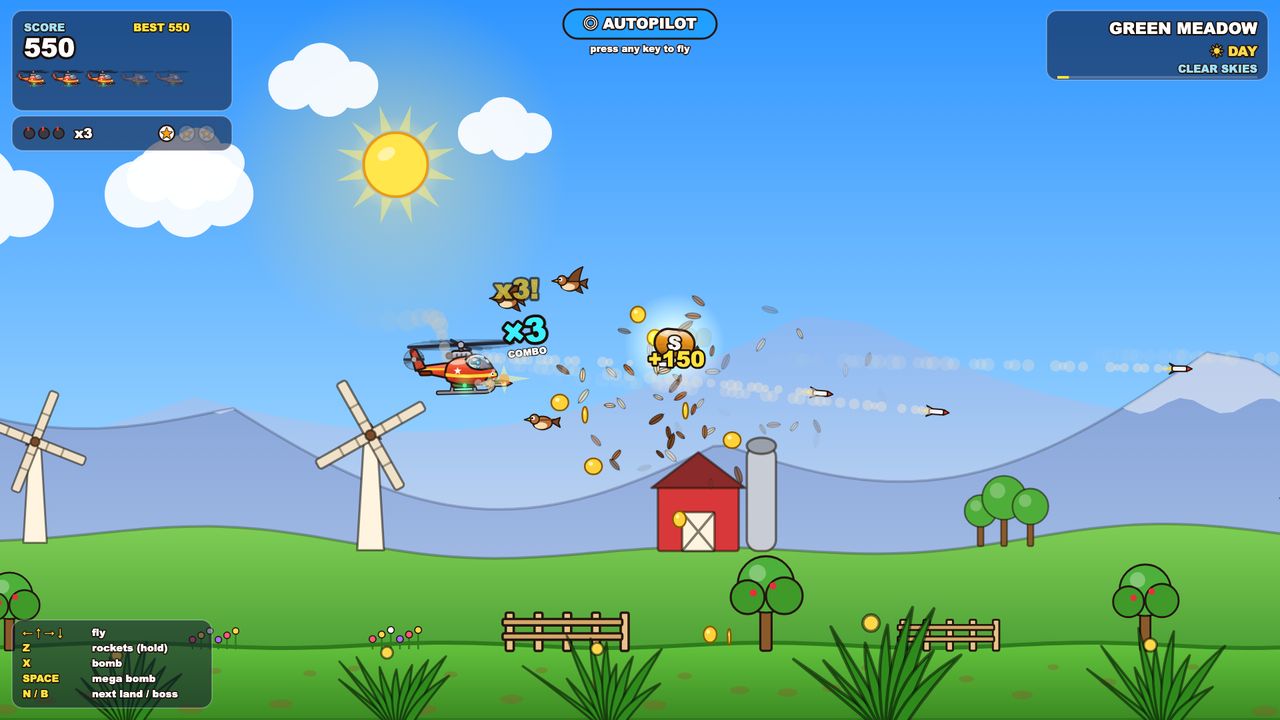 7.9
7.5/10 · engineering-1 · claude-code/claude-opus-5-5 (engineering-1 rubric)
Different rubrics; these values are historical, not a score change.